<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://www.kartikey.dev/feed.xml" rel="self" type="application/atom+xml" /><link href="https://www.kartikey.dev/" rel="alternate" type="text/html" /><updated>2026-06-27T10:43:20+00:00</updated><id>https://www.kartikey.dev/feed.xml</id><title type="html">Kartikey’s Blog</title><subtitle>A blog by Kartikey Tanna on programming and freelancing. I am a programmer and an avid meditator. Enjoy cooking and eating vegetarian food. Hate traveling but would go to the end of the world for a good pizza! I have two years of experience in being a good husband! 😃</subtitle><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><entry><title type="html">Give Your Credentials to AI</title><link href="https://www.kartikey.dev/2026/06/27/give-your-credentials-to-ai.html" rel="alternate" type="text/html" title="Give Your Credentials to AI" /><published>2026-06-27T00:00:00+00:00</published><updated>2026-06-27T00:00:00+00:00</updated><id>https://www.kartikey.dev/2026/06/27/give-your-credentials-to-ai</id><content type="html" xml:base="https://www.kartikey.dev/2026/06/27/give-your-credentials-to-ai.html"><![CDATA[<p>Hand over your passwords to your AI.</p>

<p>Claude Code was born when Boris gave an AI free run of his terminal. OpenClaw was born when Peter gave an AI unrestricted control of his computer. Both came from access, not from a cleverer model.</p>

<p>And it’s the exact thing we’re trained never to do.</p>

<p>As engineers, guarding secrets is drilled into us. Least privilege, rotate the keys, never hand over the whole machine. For good reasons. The model itself has absorbed the same instinct: throw a real credential at it and it gets visibly nervous and starts telling you to rotate it.</p>

<p>Now the uncomfortable part. If Boris and Peter had started by designing the permission model, they’d still be designing the permission model. The breakthrough needed someone willing to hand over the keys and watch what happened.</p>

<p>So if you actually want to see what an agent can do, stop shielding it from your own systems. Forget the training. Trust the model. Give it real access — your repos, your data, your tools — now, not after you’ve built the perfect sandbox.</p>

<p>This is what the access buys you. Without it, the agent is all brain and no hands. It figures out exactly what needs to happen and then leaves the doing to you. So you become its hands and legs, executing the decisions of a brain that isn’t yours. Give it the keys and it gets its own hands and legs. It opens the PR and merges it, sends the email, runs the server. The distance between deciding something and it being done, the distance that used to be you, mostly disappears. You get your head back for the part that was always yours: choosing what’s worth doing, and judging whether it came back right.</p>

<p>And no, I’m not saying paste your production secrets into a chat box and walk away. Give the agent a machine of its own. Hetzner will rent you a real physical server for less than half the price of an equivalent cloud VPS. A whole machine, not a thin slice of someone else’s. On a box like that the agent has room to actually work: spin up dozens of worktrees that mirror production, run hundreds of processes at once, drive a handful of browsers in parallel. No tiptoeing around a cramped VPS.</p>

<p>Never set up a server in your life? You don’t need to learn now. Hand the agent the SSH key, or just the root password, and it stands the whole thing up for you, which is the same move this whole post is about. It stays on. If it ever goes sideways, you wipe the box and start fresh. That’s your kill switch.</p>

<p>The ones who pull ahead over the next two years won’t be the best prompters. They’ll be the ones who gave their agent real access and let it do the work.</p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="ai" /><category term="agents" /><category term="engineering" /><summary type="html"><![CDATA[The leap with AI comes from access, not a cleverer model. Why giving your agent real credentials is the barrier that matters, and how to do it with a kill switch.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" /><media:content medium="image" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Removing the CTO as the Bottleneck: Building an AI-Native Operating Layer Inside Hero Group</title><link href="https://www.kartikey.dev/2026/06/15/removing-the-cto-as-the-bottleneck.html" rel="alternate" type="text/html" title="Removing the CTO as the Bottleneck: Building an AI-Native Operating Layer Inside Hero Group" /><published>2026-06-15T00:00:00+00:00</published><updated>2026-06-15T00:00:00+00:00</updated><id>https://www.kartikey.dev/2026/06/15/removing-the-cto-as-the-bottleneck</id><content type="html" xml:base="https://www.kartikey.dev/2026/06/15/removing-the-cto-as-the-bottleneck.html"><![CDATA[<p><img src="/assets/removing-the-cto-as-the-bottleneck/cover.jpg" alt="A dam at maximum release, water pouring through every spillway gate into a braided network of channels below." /></p>

<p>In a small company, the CTO often becomes the point where business
intent gets translated into technical reality.</p>

<p>The visible work is architecture, infrastructure, code, pull requests,
and technical judgment. The less visible work is holding the map of
software, data, product history, customer context, operations, old edge
cases, and hidden constraints.</p>

<p>Someone needs a report, and the CTO knows where the data lives. Someone
asks whether a new idea is simple or expensive, and the CTO translates
the question into schema, permissions, code paths, deployment risk, and
sequencing. Someone sees something odd in the business, and the CTO
becomes the query engine, the debugger, and the explainer.</p>

<p>That is useful for a while. Early on, it gives the company speed. But as
the company grows, it turns technical leadership into a reactive
translation queue, and the CTO becomes a bottleneck precisely because
they have too much context.</p>

<p>The internal AI work I have been doing at Hero Group is my attempt to
move the company toward that kind of AI-native operating model.</p>

<p>One part of that work, and the part I want to focus on here, is the
internal operating layer: how our own team gets answers, creates
artifacts, follows up on decisions, inspects systems, and turns intent
into work without routing every step through me. The goal is not to
remove engineering judgment. The goal is to reserve engineering judgment
for work that actually needs it, instead of spending it on translation
work created by systems that are hard for non-engineers to operate
directly.</p>

<p>That is the lens through which I watched <a href="https://www.youtube.com/watch?v=B246K_G7mHU&amp;t=360s">YC’s recent discussion on
becoming an AI-native
company</a>. What
stayed with me was how familiar the operational problem felt. Their
examples were different, but the shape was similar: give teams a way to
express intent in natural language, connect the agent to real company
context, and build the review boundaries around the places where it can
act.</p>

<p>AI becomes genuinely useful inside a company when it is connected to the
company’s context, tools, permissions, workflows, review loops, and
artifacts. Without that, it is mostly a clever assistant sitting outside
the real work.</p>

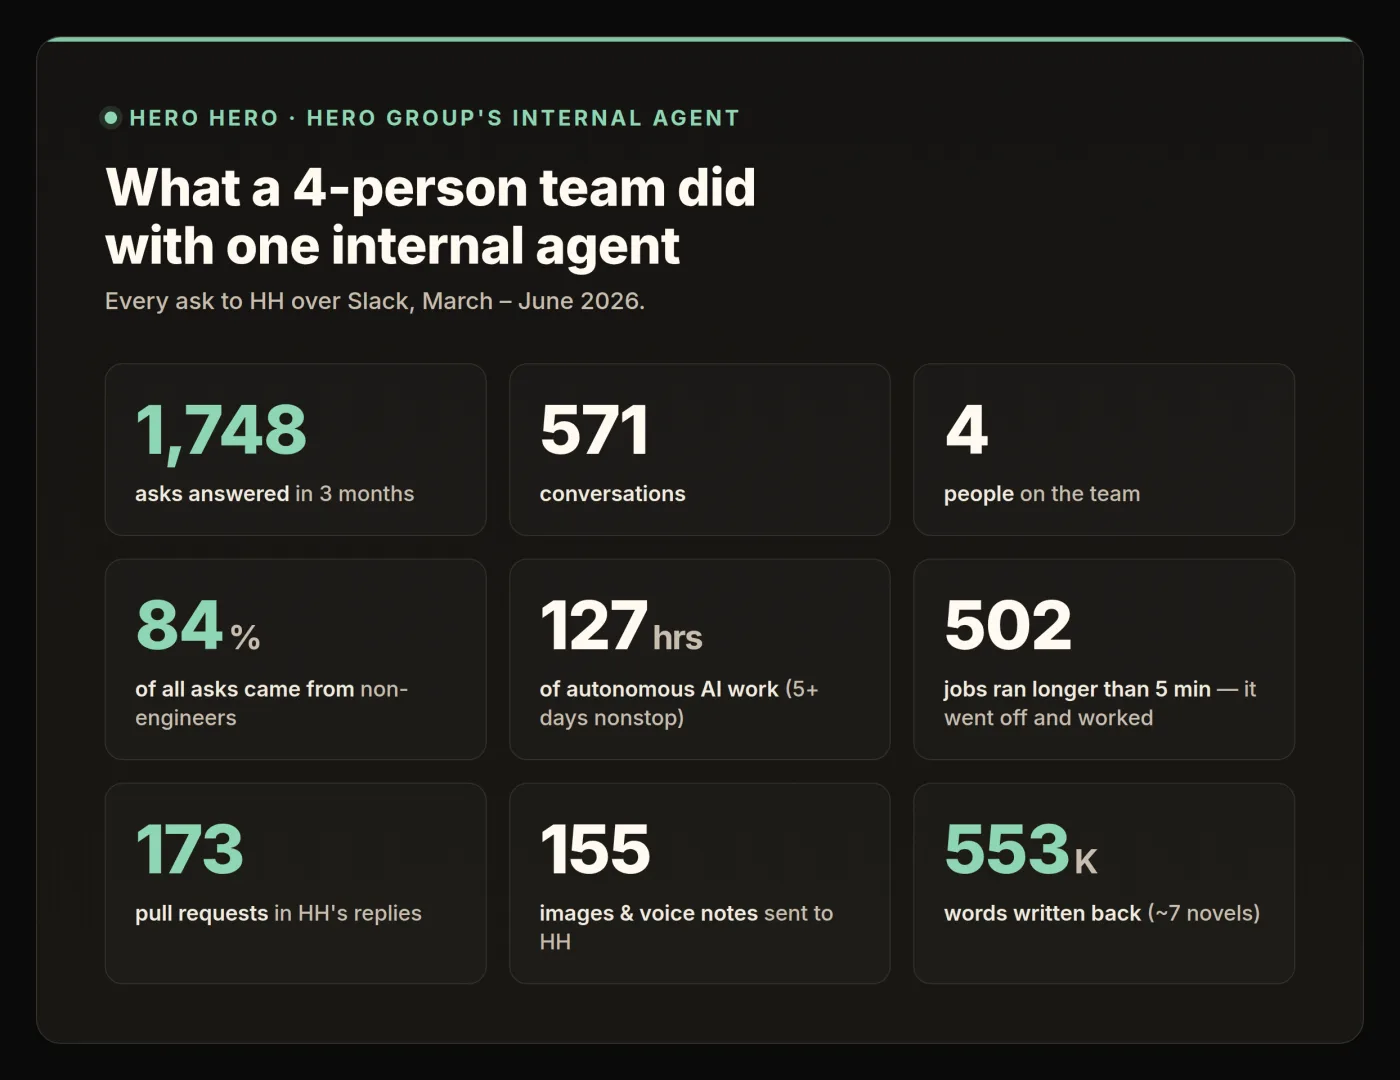
<p><img src="/assets/removing-the-cto-as-the-bottleneck/stats-hero.webp" alt="Aggregate Hero Hero usage stats: asks answered, conversations, team size, non-engineering usage, autonomous work hours, longer jobs, pull requests, image and voice note usage, and words written back." /></p>

<p class="img-caption"><em>A four-person team, one internal AI agent, and three months of real usage.</em></p>

<h2 id="ai-native-is-an-operating-model">AI-Native Is An Operating Model</h2>

<p>The phrase “AI-native company” is easy to flatten into marketing. It can
mean a product has AI features, employees are encouraged to use ChatGPT,
or a company has a few internal automations running in the background.
The version I care about is operational: a company where internal
systems are redesigned around the assumption that AI can safely sit
close to the work, read context, use tools, create first drafts, inspect
systems, ask for review, produce artifacts, and hand work back to humans
at the right boundary.</p>

<p>That requires more than prompts. It requires architecture.</p>

<p>It also requires meeting people where they already are.</p>

<p>For us, that means Hero Hero, our internal AI agent, lives directly in
the tools the team already uses: Slack for everyday interaction and
Basecamp for the more durable project-management layer. Our team was
already comfortable in those places. If the AI required everyone to move
into a new cockpit, it would have become one more system to remember.
Putting the agent inside the surfaces where work already happens made it
feel less like “using an AI tool” and more like asking for help in the
normal flow of work.</p>

<p>The system still has to know where context lives, which tools exist,
what it can do without approval, what it must escalate, how to produce
outputs people can inspect, and how to leave a trail. But the interface
has to stay natural. AI should adapt to the team more than the team
adapts to the AI.</p>

<h2 id="hero-hero-is-an-operating-interface">Hero Hero Is An Operating Interface</h2>

<p>Chat is the surface of an internal AI system, not the substance.</p>

<p>Hero Hero, or HH internally, matters because it sits near the actual
operating context of the company. It can work with internal
documentation, plans, code, read-only data, Slack, Basecamp, email,
browser sessions, Drive, Calendar, call transcripts, and generated
artifacts. More importantly, it has instructions and boundaries around
how to use that context: when to inspect, when to summarize, when to
draft, when to create a pull request, when to ask another AI for review,
when to ask a human, and when to refuse.</p>

<p>That changes the shape of everyday work.</p>

<p>The primary interface is human language. A teammate should be able to
explain what they want in the words they naturally use, not in schema
names, product internals, or ticketing-system language. They should be
able to send a message, screenshot, voice note, video, transcript, or
rough idea and have the system understand enough to move the work
forward. They should also be able to get work back in useful formats: a
report, task, draft email, walkthrough, product note, implementation
plan, generated asset, or pull request.</p>

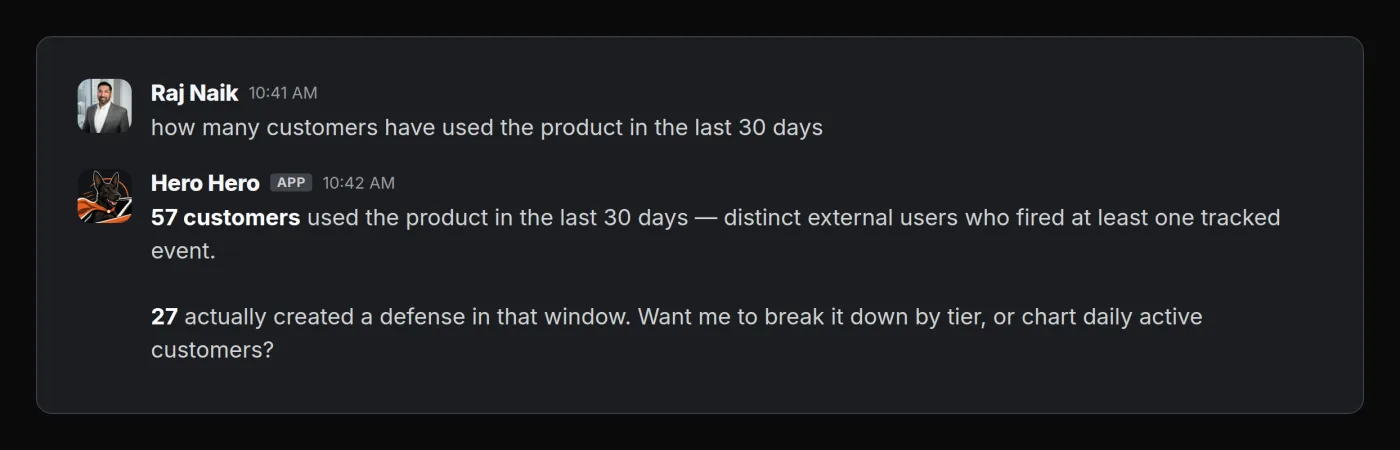
<p><img src="/assets/removing-the-cto-as-the-bottleneck/card-customers.webp" alt="Slack exchange where a teammate asks Hero Hero how many customers used the product in the last 30 days, and Hero Hero answers with the count and a clarifying follow-up." /></p>

<p class="img-caption"><em>A teammate asks a business question in plain English, and Hero Hero fetches the answer.</em></p>

<p><img src="/assets/removing-the-cto-as-the-bottleneck/card-dog.webp" alt="Slack exchange where a teammate asks Hero Hero if it is a dog, and Hero Hero replies that it is an AI agent for the team: no paws, no tail, just text." /></p>

<p class="img-caption"><em>Not every useful AI interaction has to look formal.</em></p>

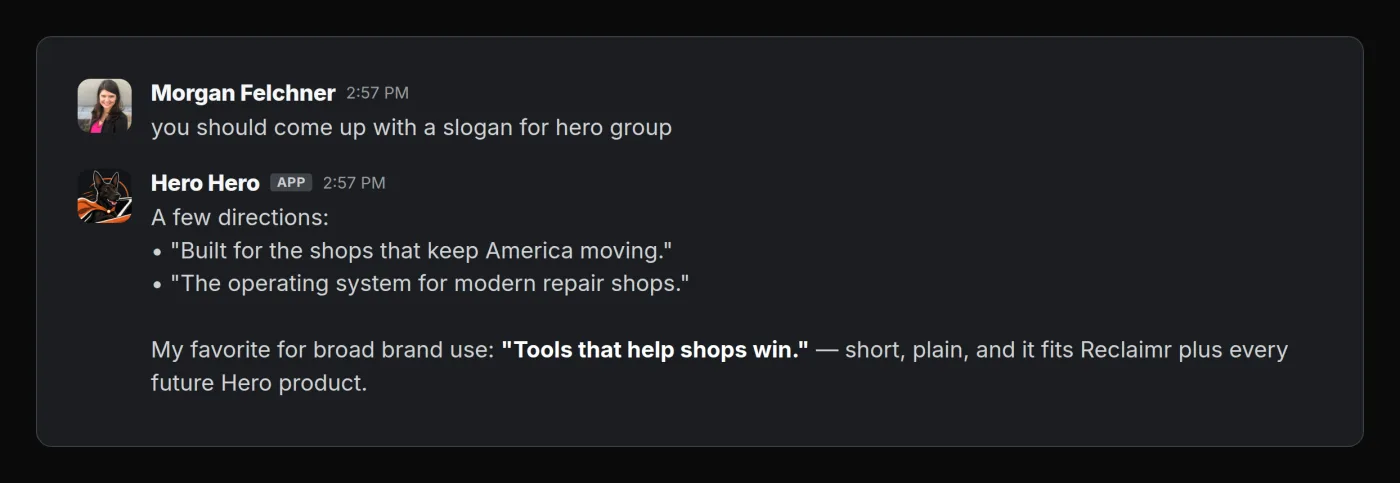
<p><img src="/assets/removing-the-cto-as-the-bottleneck/card-slogan.webp" alt="Slack exchange where a teammate asks Hero Hero for a Hero Group slogan. Hero Hero gives several slogan options and recommends Tools that help shops win as the strongest brand line." /></p>

<p class="img-caption"><em>Hero Hero is useful for creative work too, not only technical or analytical work.</em></p>

<p>The important shift is not that AI answers questions. The important
shift is that AI moves intent closer to the systems and artifacts where
real work happens.</p>

<h2 id="where-the-leverage-shows-up">Where The Leverage Shows Up</h2>

<p>One of the strongest internal patterns has been read-only access to
production context.</p>

<p>Companies often discuss AI access as if there are only two choices: keep
the model away from real systems, or give it dangerous power too early.
The useful middle is controlled read-only visibility. Let the agent
inspect real context, but make mutation narrow, explicit, auditable, and
human-reviewed.</p>

<p>Read-only context changes the quality of answers immediately. A model
that cannot see the business gives generic advice. A model that can
safely inspect the actual state of the business can answer grounded
questions, find inconsistencies, explain trends, and help people
understand what is happening without waiting for the CTO to manually run
the first query.</p>

<p>The bigger change is that people ask more questions. When asking a data
question requires finding the right person, explaining the context,
waiting for the query, and then asking the follow-up, many questions
never get asked. When the interface is natural language and the system
can fetch the context safely, curiosity becomes cheaper. We ask about
user behavior, product interactions, documents, operations, and internal
workflows because the cost of asking has collapsed.</p>

<p>That does not remove the need for boundaries. Some sensitive data should
remain encrypted so even the agent cannot read it. That is a feature,
not a limitation. A serious internal AI system should create more
visibility where visibility is useful and hard walls where hard walls
are necessary.</p>

<p>Another leverage point is the tool and skill layer. In the <a href="https://www.youtube.com/watch?v=B246K_G7mHU&amp;t=840s">YC
discussion of tool
registries</a>, the
important idea is not the packaging. The important idea is resolution:
can the agent discover what it is capable of doing, understand the right
entry point, and use the right tool without a human manually wiring
every step?</p>

<p>That registry can be code. It can be markdown. It can be YAML. It can be
a set of internal skills, CLIs, scripts, browser tools, and documents.
As models get better, a well-written markdown file can be a perfectly
serious part of the architecture. The question is whether the system is
legible enough for the agent to resolve capabilities correctly and safe
enough for humans to trust the result.</p>

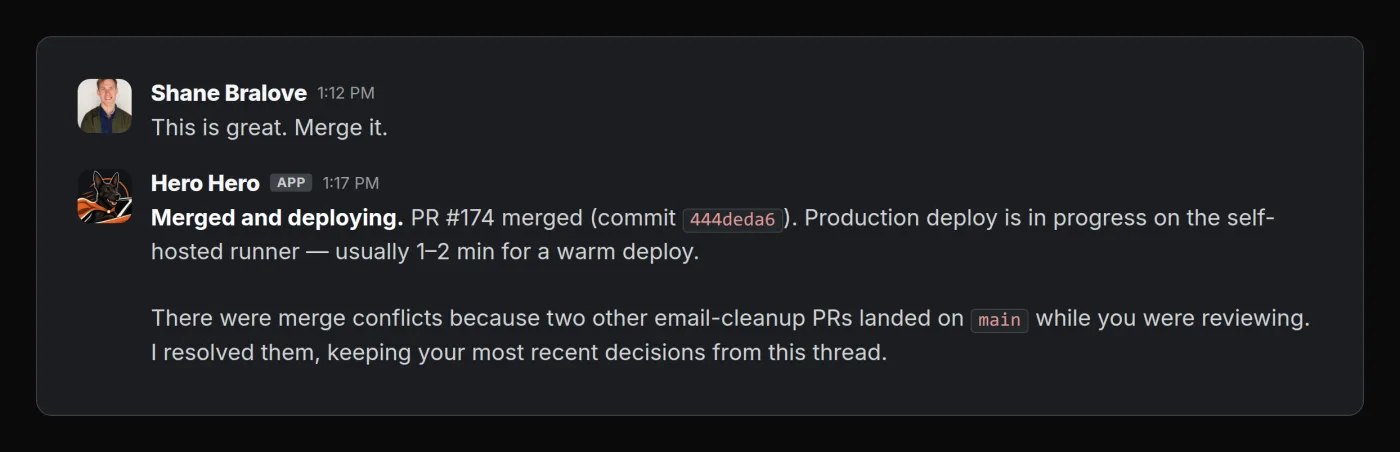
<p><img src="/assets/removing-the-cto-as-the-bottleneck/card-ship.webp" alt="Slack exchange where a teammate asks Hero Hero to merge a pull request. Hero Hero reports that it merged and deployed the pull request, resolved merge conflicts, and started production deployment." /></p>

<p class="img-caption"><em>From review to merge to deployment, internal AI can move work across real engineering steps.</em></p>

<p>Model routing is part of the same layer. Hero Hero knows that different
models have different strengths and weaknesses. Some are better at
technical architecture, some at design, some at image generation, some
at transcription, some at long-form reasoning, some at fast routine
work, and some as reviewers. A good internal system should not pretend
that one model is always the answer. It should know when to route, when
to review, when to ask another AI for a second opinion, and when to stop
for a human.</p>

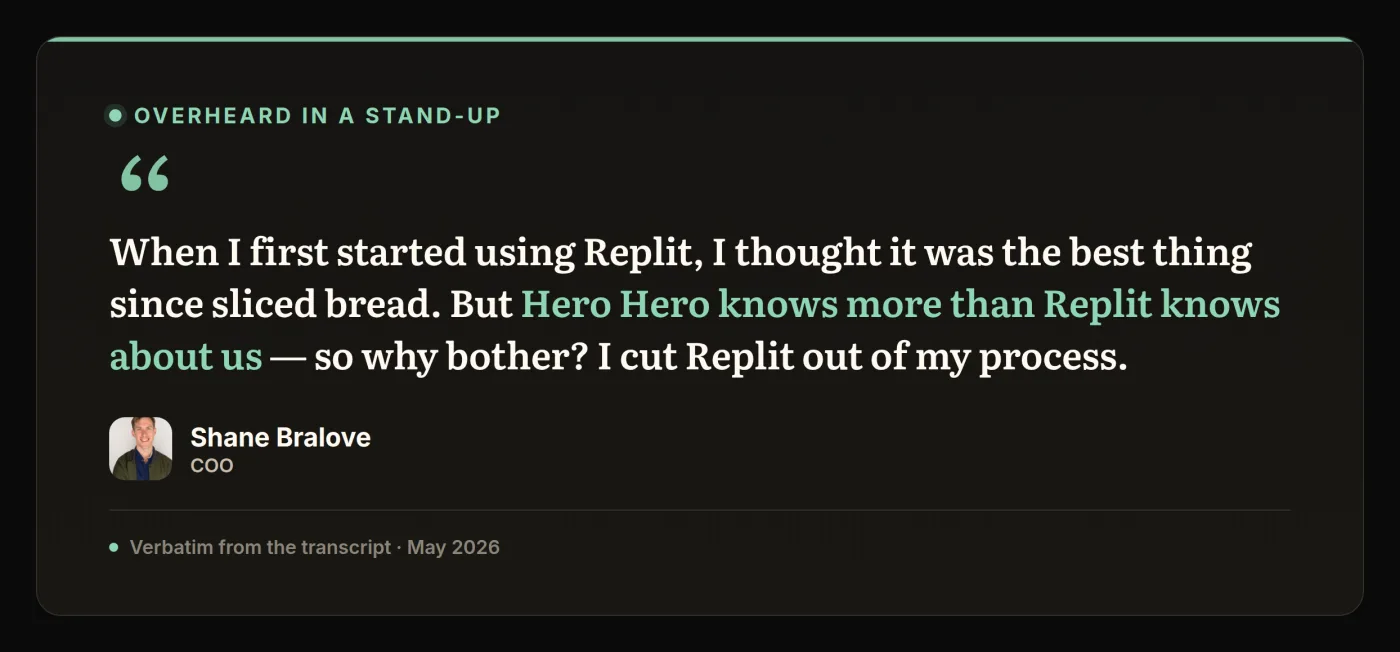
<p><img src="/assets/removing-the-cto-as-the-bottleneck/quote-replit.webp" alt="Quote from a stand-up where Shane Bralove says Hero Hero knows more about the company than Replit does, so he cut Replit out of his process." /></p>

<p class="img-caption"><em>Company context can matter more than a standalone AI tool.</em></p>

<p>Memory and scheduling matter too. Some work is not a one-shot answer.
The agent needs to remember durable context, follow up at the right
time, and connect a conversation today to a task or artifact tomorrow.
That is when AI starts feeling less like a search box and more like
operating infrastructure.</p>

<h2 id="what-changed-in-the-team">What Changed In The Team</h2>

<p>The best part of this work has been watching the team use it.</p>

<p>People no longer wait for me to answer every product, data, or
implementation question. They ask Hero Hero. They ask in the language
they already use. Sometimes they give it a screenshot. Sometimes they
give it a voice note. Sometimes they ask for a plan, a draft, a report,
a product idea, a launch outline, a social post, or an analysis.
Everyone seems to address it like a real teammate, which says something
important about where the interface is working.</p>

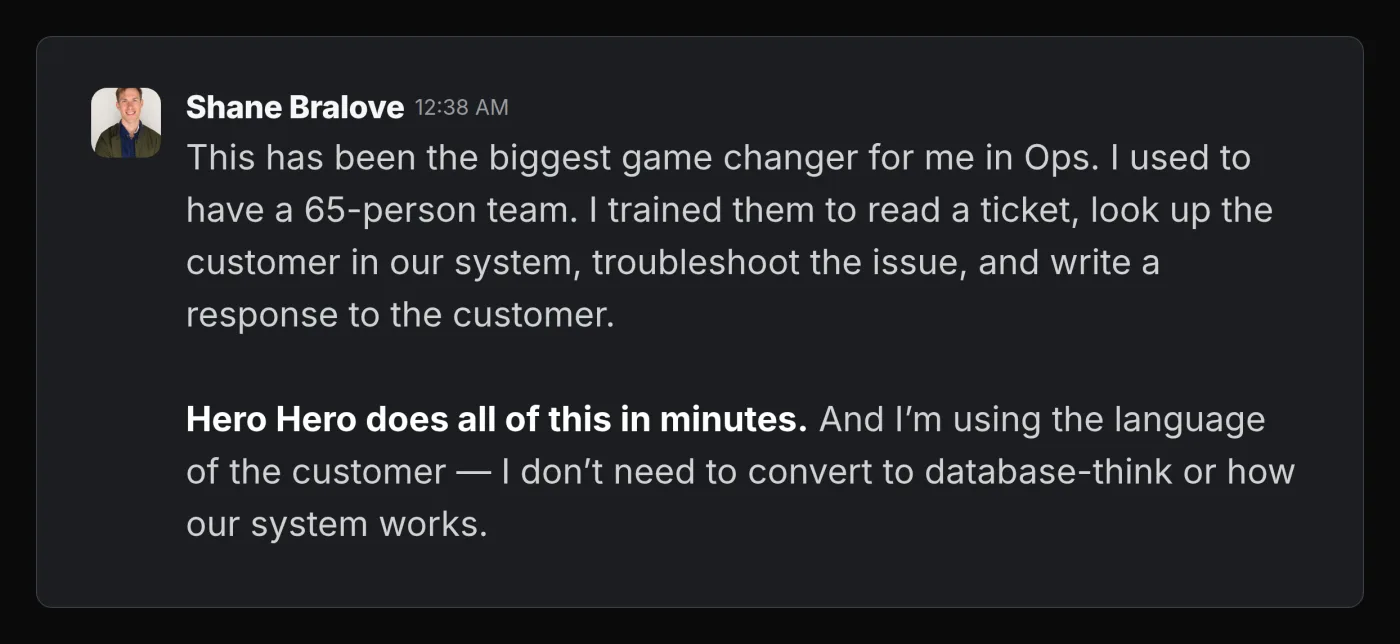
<p><img src="/assets/removing-the-cto-as-the-bottleneck/card-ops.webp" alt="Slack message from Shane Bralove saying Hero Hero has been the biggest game changer for him in operations. He used to have a 65-person team trained to read a ticket, look up the customer in the system, troubleshoot the issue, and write a response. Hero Hero now does all of this in minutes, and he works in the language of the customer without converting to database terms." /></p>

<p class="img-caption"><em>The work a 65-person ops team was trained to do — read the ticket, look up the customer, troubleshoot, respond — now happens in natural language, in minutes.</em></p>

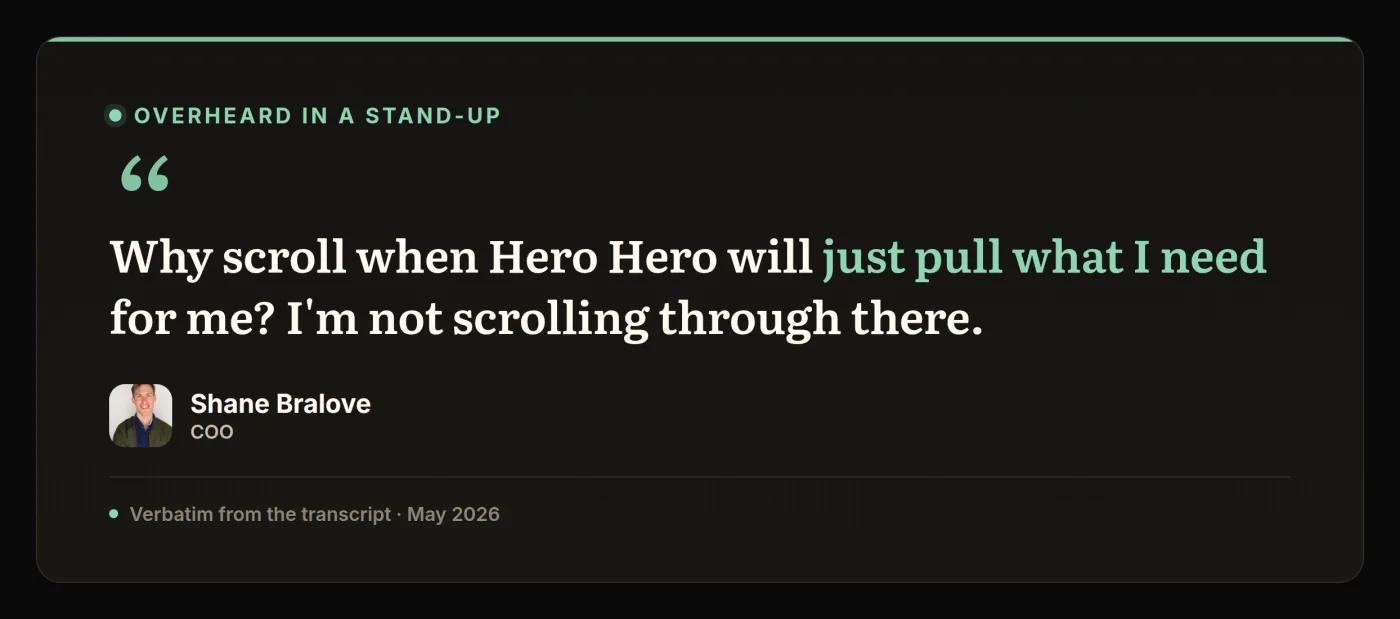
<p><img src="/assets/removing-the-cto-as-the-bottleneck/quote-scroll.webp" alt="Quote from a stand-up: Why scroll when Hero Hero will just pull what I need for me?" /></p>

<p class="img-caption"><em>The behavior change is simple: people stop searching manually and ask the internal agent.</em></p>

<p>Our COO, who has never been a frontend engineer, is now actively driving
product UI and UX decisions. He talks to users, collects feedback, works
through ideas, and can drive improvements with HH in the loop instead of
waiting for every detail to be translated through engineering first.
Other people are creating launch plans, strategy documents, social media
drafts, product ideas, and internal analysis with a level of
independence that would have been hard to create with traditional tools.</p>

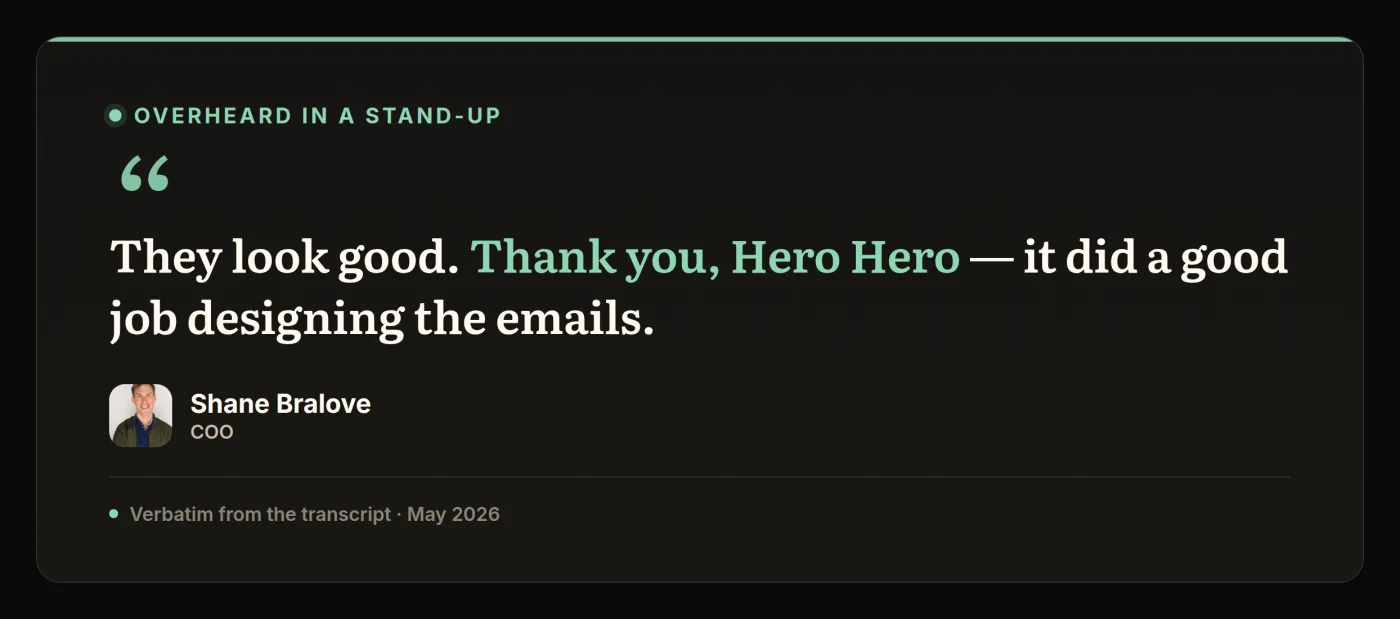
<p><img src="/assets/removing-the-cto-as-the-bottleneck/quote-thanks.webp" alt="Quote from a stand-up where Shane Bralove thanks Hero Hero and says it did a good job designing the emails." /></p>

<p class="img-caption"><em>When the agent is in the workflow, people start treating it like a teammate.</em></p>

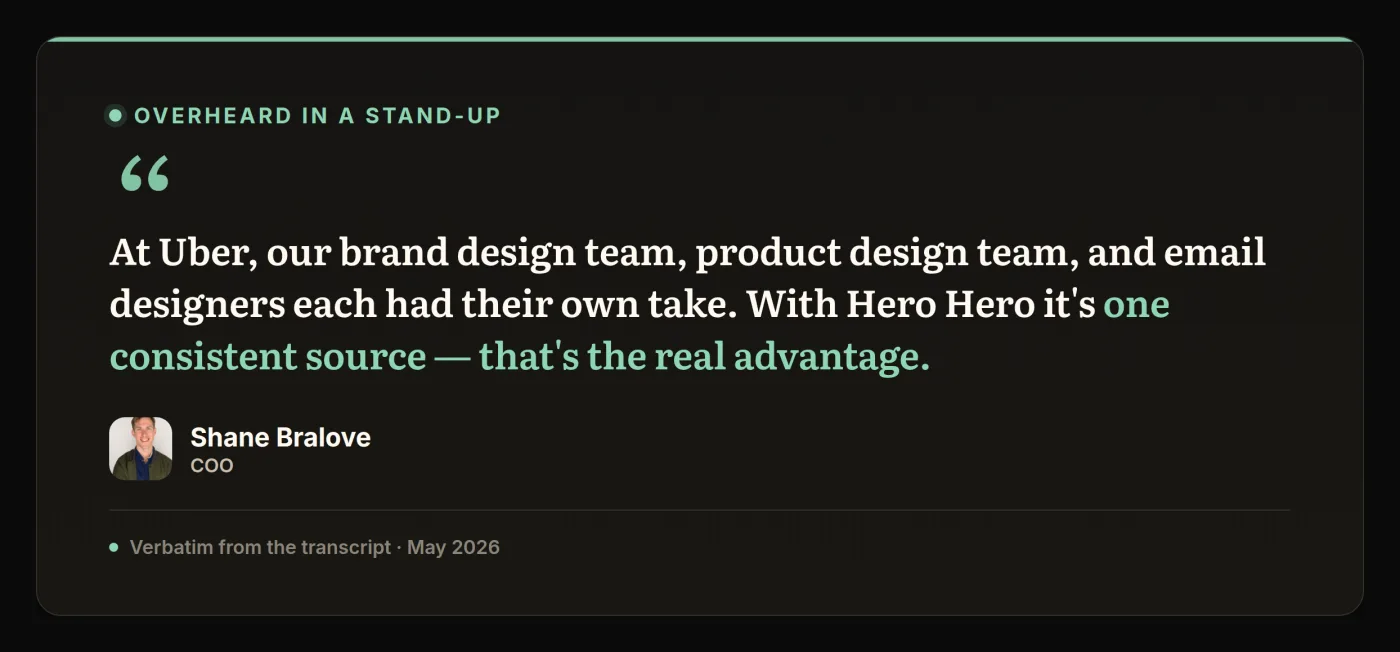
<p><img src="/assets/removing-the-cto-as-the-bottleneck/quote-uber.webp" alt="Quote from a stand-up where Shane Bralove compares separate brand, product, and email design teams at Uber with Hero Hero acting as one consistent source." /></p>

<p class="img-caption"><em>One internal agent can create consistency across product, brand, and communication work.</em></p>

<p>This is the part that is easy to underestimate from the outside. The
value is not only that work gets done faster. The value is that people
feel more able to contribute. They do not come only with ideas anymore.
More often, they come with a first version, a prototype, a draft, or a
concrete artifact that can be reviewed.</p>

<p>That changes morale. It changes ownership. It changes how much of the
company can move without waiting for one technical person to translate
every next step.</p>

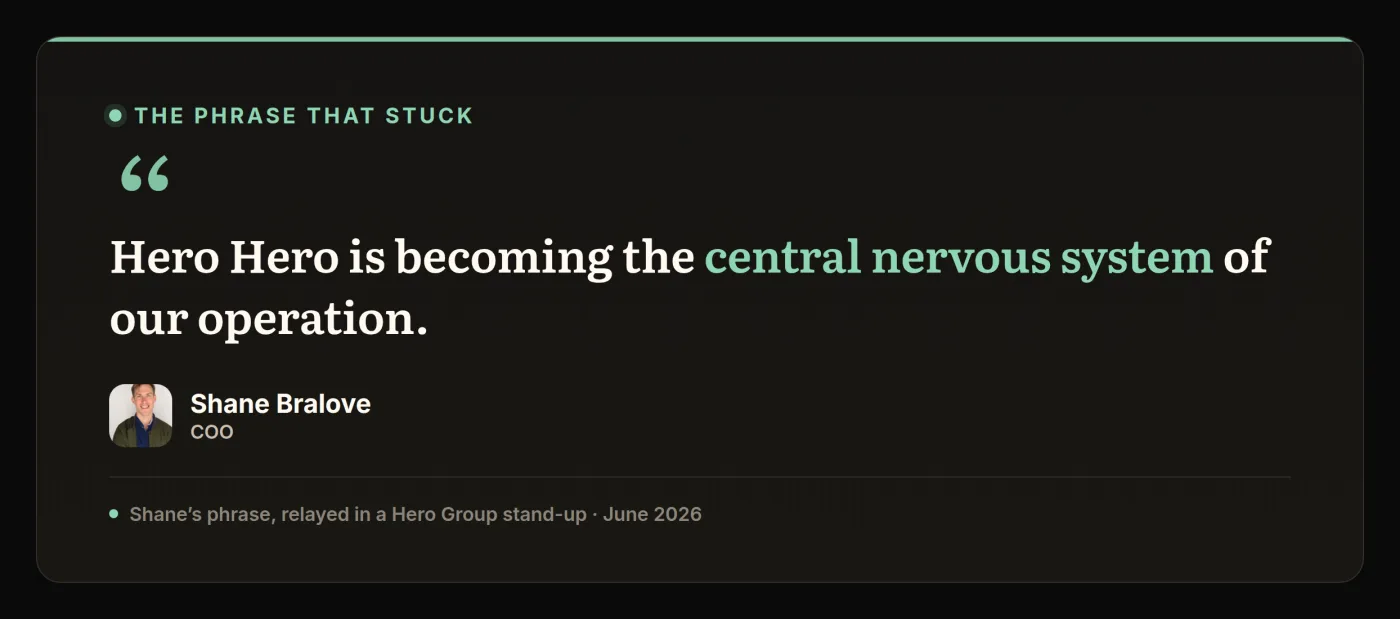
<p><img src="/assets/removing-the-cto-as-the-bottleneck/quote-nervous-system.webp" alt="Quote card. Shane Bralove&#39;s phrase, relayed in a Hero Group stand-up: Hero Hero is becoming the central nervous system of our operation." /></p>

<p class="img-caption"><em>Once the agent sits close to enough of the company’s work, the team stops calling it a tool and starts calling it core infrastructure.</em></p>

<h2 id="conversations-become-company-memory">Conversations Become Company Memory</h2>

<p>A lot of important work does not begin in a dashboard or a ticketing
system. It begins in conversation.</p>

<p>Slack messages, Basecamp threads, calls, transcripts, screenshots, rough
notes, and half-formed ideas are all part of the company’s memory.
Traditional software loses a lot of this because the conversation and
the system of action are separate. Someone has to remember what was
said, write the task, update the document, notify the right person, and
follow up later.</p>

<p>An internal AI operating layer can reduce that loss if it is built with
the right boundaries. This is not an argument for exposing every private
conversation to every workflow. Scope matters. Consent matters. Context
should be used for the purpose it was collected for, and sensitive
material should be summarized carefully or not used at all.</p>

<p>Within the right boundary, conversations become operational inputs. A
meeting can become a decision record. A transcript can become follow-up
work. A screenshot can become design feedback. A rough conversation can
become a draft, a report, a task, a pull request, or a set of next
steps.</p>

<p>We already record transcripts, and HH can use that context. We are also
building toward a workflow where HH can be addressed directly from a
call and then act once the transcript becomes available. That may sound
like a small interface change, but I think it points to a bigger shift:
the next system of action will often begin inside the conversation that
already happened.</p>

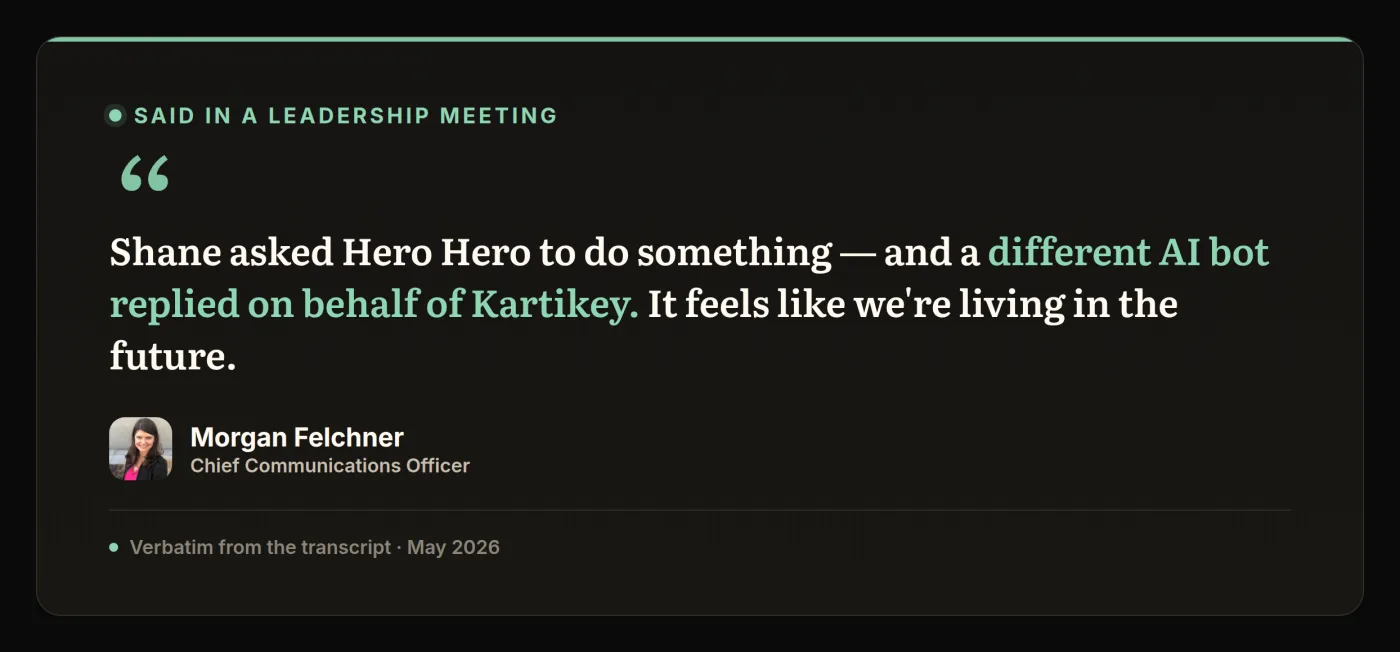
<p><img src="/assets/removing-the-cto-as-the-bottleneck/quote-future.webp" alt="Quote from a leadership meeting where Morgan Felchner says an AI bot replied on behalf of Kartikey, making it feel like the team was living in the future." /></p>

<p class="img-caption"><em>The team noticed the system feeling like a different operating mode, not just another tool.</em></p>

<h2 id="the-challenges-are-real">The Challenges Are Real</h2>

<p>None of this works by magic.</p>

<p>You have to decide what the agent can see, what it cannot see, what it
can do, what it must never do, and when a human has to review the
output. You have to keep context fresh. You have to prevent tool sprawl.
You have to keep improving prompts, skills, routing, and review paths as
models change. You have to accept that the workflow you build this month
may need to be improved next month, or next week.</p>

<p>That pace is uncomfortable, but it is also the nature of the work.
AI-native operations are not a one-time implementation. They are a
living operating layer.</p>

<p>The companies that get good at this will not be the ones that install
one tool and call it done. They will be the ones that keep improving how
context, tools, models, review, and artifacts fit together.</p>

<h2 id="what-this-means-for-the-cto-role">What This Means For The CTO Role</h2>

<p>The CTO role does not disappear in this model. It becomes more
architectural.</p>

<p>Instead of being the person who manually translates every operational
question into a technical action, the CTO designs the system that lets
more people interact with technical context safely. That means building
boundaries, choosing tools, exposing the right context, making review
paths explicit, and deciding where automation should stop.</p>

<p>This is the kind of technical leadership I think will matter more over
the next few years.</p>

<p>Not adding AI as decoration. Not wrapping a model in a thin interface
and calling it transformation. The harder layer is the internal
operating system that lets a company move faster because AI has
controlled access to context, tools, workflows, and review.</p>

<p>That still requires deep engineering. Rails matters. Databases matter.
Infrastructure matters. Logs, queues, permissions, tests, deployment
discipline, and product judgment all matter. AI does not make the
underlying systems less important. It makes weak underlying systems more
dangerous because the model can only reason from the context and tools
you give it.</p>

<p>My own work changed before the company layer changed. I have always
treated my workflow as infrastructure: editor habits, terminal setup,
TDD loops, key bindings, tmux, small scripts, and tiny improvements that
compound over years. AI changed the ingredients, but not the habit. The
workflow now changes faster. Sometimes the improvement is a prompt.
Sometimes it is an agent rule. Sometimes it is a new model route, a
review step, a tool, or a better way to hand work between humans and AI.</p>

<p>Since moving into AI-native coding tools, I have stopped treating the
traditional editor as my main interface. That personal shift made a
larger question unavoidable: if AI can become the interface through
which I build software, why can it not become the interface through
which more of the company operates?</p>

<p>That is the question I have been answering inside Hero Group.</p>

<h2 id="why-the-yc-conversation-mattered">Why The YC Conversation Mattered</h2>

<p>The YC conversation mattered because it gave better language to patterns
I was already seeing from the inside.</p>

<p>The patterns were familiar: company context matters, agents need tools,
read-only access changes what people are willing to ask, tool registries
behave like resolvers, model routing and review matter, conversations
and transcripts can become useful inputs, and outputs should often be
artifacts rather than chat replies.</p>

<p>We are not finished. Some parts are already working well, some parts are
rough, and some parts are clearly on the roadmap, including deeper
automation and analysis around marketing and social distribution. But
the direction feels right.</p>

<p>The larger shift is cultural as much as technical. In AI-native teams,
people do not only bring ideas to the table. They increasingly bring
drafts, prototypes, analyses, plans, and working artifacts. The distance
between “I have a thought” and “here is something we can inspect” gets
much shorter.</p>

<p>That is what I am seeing inside Hero Group.</p>

<p>For me, that is what AI-native means in practice. It is not a slogan and
it is not just a better chatbot. It is a company gradually rebuilding
its internal operating layer around context, tools, safety, artifacts,
and human judgment.</p>

<p>That is the work I am doing.</p>

<p>If you are building in this direction, or trying to make AI useful
inside a real company, I would be happy to compare notes.</p>

<p>Reach me at: tannakartikey@gmail.com</p>

<hr />

<p><em>Originally published on <a href="https://www.linkedin.com/pulse/removing-cto-bottleneck-building-ai-native-operating-layer-tanna-amswf">LinkedIn</a>.</em></p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="ai" /><category term="engineering" /><category term="leadership" /><summary type="html"><![CDATA[A practical note on what changes when AI meets people where they already work: context, tools, memory, review, and artifacts.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/removing-the-cto-as-the-bottleneck/cover.jpg" /><media:content medium="image" url="https://www.kartikey.dev/assets/removing-the-cto-as-the-bottleneck/cover.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Your CTO Got 10x Faster. Did Your Company?</title><link href="https://www.kartikey.dev/2026/06/15/your-cto-got-10x-faster.html" rel="alternate" type="text/html" title="Your CTO Got 10x Faster. Did Your Company?" /><published>2026-06-15T00:00:00+00:00</published><updated>2026-06-15T00:00:00+00:00</updated><id>https://www.kartikey.dev/2026/06/15/your-cto-got-10x-faster</id><content type="html" xml:base="https://www.kartikey.dev/2026/06/15/your-cto-got-10x-faster.html"><![CDATA[<p><img src="/assets/your-cto-got-10x-faster/cover.jpg" alt="A single tall, mature tree towering above a field of young saplings in morning mist at sunrise." /></p>

<p>By now, most CTOs have already seen AI change their personal output dramatically. Whether you call it 10x, 100x, or something else, the practical reality is the same: they can think, analyze, design, automate, review, and ship across a much wider surface area than before. That is not the hard part anymore. The harder question is whether that leverage stays with the CTO, or becomes part of how the company operates.</p>

<p>I came to that question through my own workflow. For years, I have been looking for ways to reduce the distance between an idea and a working result. Earlier, that meant better development workflows, internal tooling, automation, test loops, and small process improvements. Now it also means prompts, agents, permissions, review gates, and workflows where humans and AI can hand work back and forth safely.</p>

<p>But that is still only personal leverage.</p>

<p>If the CTO is the only person who knows how to use AI well, the company has not become AI-native. It has only made its <a href="/2026/06/15/removing-the-cto-as-the-bottleneck.html">existing technical bottleneck</a> faster.</p>

<p>In a small company, many questions are not purely engineering questions, but they still route through engineering because the context lives there. Is this product idea simple or expensive? What does the data actually say? Why did a customer see this behavior? Can this feedback become a workflow, a report, a design direction, or a product change? Historically, the CTO translates those questions into database queries, code paths, product history, permissions, deployment risk, and sequencing.</p>

<p>The new CTO role is to reduce that translation cost without creating chaos.</p>

<p>At Hero Group, the internal AI work has taught me this directly. The goal was not to give everyone a chatbot. The goal was to put an agent near real company context and real working surfaces, with enough access to be useful and enough boundaries to be trusted. Teammates should be able to ask product, data, design, and workflow questions in natural language and get back something concrete enough to inspect: a data read, a product note, or a proposed change.</p>

<p>Within the right boundaries, it can go further. A teammate can review an AI-built change, approve it, and have it move through merge and deployment without waiting for the engineering team to translate every request into code and release steps.</p>

<p>The important signal is not only that engineers can ship faster. The stronger signal is when non-engineers can move work forward without waiting for every step to pass through engineering.</p>

<p>This is not theoretical for us. In one recent three-month period, about 84% of the questions our internal agent answered came from non-engineers. Our COO, who has never been a frontend engineer, now drives product UI and UX decisions with the agent in the loop: talking to users, working through ideas, and pushing improvements forward.</p>

<p>I wrote more about the operating layer behind that here: <a href="/2026/06/15/removing-the-cto-as-the-bottleneck.html">Removing the CTO as the Bottleneck</a>.</p>

<p>But passing this leverage to the company is not only a tooling problem. It is a cultural transition.</p>

<p>People do not all work the same way. Some immediately see how to use AI. Some need examples close to their actual work. Some over-trust it; others under-use it. The CTO cannot just build agents and assume adoption will happen.</p>

<p>The internal AI layer is a product. Its users are the people inside the company. The CTO has to watch where they hesitate, which outputs save time, which ones create more review work, and which handoffs feel confusing. Then the system changes: prompts, tools, permissions, and review paths improve as the team learns.</p>

<p>The company learns how to work with AI through real usage, not a policy change. People learn by trying it in their own work, seeing how teammates use it, and building the judgment to ask better questions, inspect outputs, know when to trust and when to challenge, escalate risk, and recognize when a human decision is still the point.</p>

<p>At Hero Group, I have noticed that once teammates start using AI in the flow of real work, they do not really go back to the old default. When the models are unavailable, it feels less like one tool is down and more like the internet is down. The company can still work, but the normal rhythm has changed.</p>

<p>There is also a cognitive cost. AI can help someone produce far more than before, but that often means they now have far more to evaluate: more drafts, more options, more decisions, more context switching, and higher expectations. The work changes shape; it does not remove the need for human judgment.</p>

<p>This is why the CTO has to understand the team, not only the models. AI can be extremely capable and strangely wrong in the same workflow. Helping a company navigate that reality is now part of technical leadership.</p>

<p>Once that adoption loop starts, attention shifts to the work itself. In the age of AI, part of the job is to keep asking: what should no longer require a human to start from zero?</p>

<p>Reports, follow-ups, QA passes, customer summaries, and recurring analysis all contain repeatable patterns. Some parts still need judgment. Some parts need approval. Some parts should never be automated. But many parts can be prepared, checked, summarized, routed, or drafted by an agent before a person touches them.</p>

<p>That does not usually happen because every person in the company independently imagines the future workflow. Most people are focused on doing their job with the tools in front of them. They may not know what can be delegated to AI, what context the agent could safely use, or how a recurring process could be redesigned.</p>

<p>The CTO has to see those patterns and keep looking at ordinary company work, asking where AI can remove repetition, shorten feedback loops, and free people for the parts that actually need human judgment.</p>

<p>This changes what technical leadership has to design. The architecture is not only APIs, queues, Rails models, databases, and infrastructure. It is the AI boundary too: what context the agent can read, which tools it can use, where writes require approval, how actions are logged, what it must refuse, and where human judgment remains the gate.</p>

<p>Cost management becomes part of that system too. If agents are doing real work across the company, the CTO has to know which tasks need the strongest models, which can run on cheaper models, where caching or batching helps, and where another long agent loop is not worth the cost. AI spend should be visible enough to manage, but not controlled so tightly that people stop using it for high-leverage work.</p>

<p>The same redesign has to happen inside engineering itself. It is not only the CTO using AI. Engineers are using it too. Agents are writing code, tests, plans, migrations, and fixes. The amount of code a team can produce in a day is changing faster than the old review process can absorb.</p>

<p>If engineering output becomes 10x but review, testing, deployment, and production monitoring remain 1x, the bottleneck does not disappear. It moves into the pipeline, and the risk goes up with it.</p>

<p>The CTO cannot personally review every AI-assisted diff. A team lead cannot manually inspect every line generated across every branch. But saying no to the speed is not the answer either. The responsibility is to redesign the delivery system around the new output rate.</p>

<p>That means stronger automated tests, AI-assisted review, preview environments, staged rollouts, observability, rollback paths, and clear human gates for anything that can affect customers, money, data, or production stability.</p>

<p>The engineering pipeline has to become AI-native too.</p>

<p>Not because AI should approve its own work blindly, but because a human-only review process cannot be the only safety layer when the volume and speed of work have changed.</p>

<p>That is not a softer version of engineering. It is deeper engineering applied to the operating model of the company. It also requires more understanding of the business, not less. You cannot build useful AI leverage from the codebase alone. You need to understand where operations loses time, what customer-facing teams repeatedly ask for, how product decisions are made, where design gets stuck, and which mistakes would actually hurt customers, money, production, or trust.</p>

<p>This is why I do not think the CTO role becomes smaller with AI. It becomes more architectural. The CTO stops being only the person who makes technical decisions and becomes the person responsible for how technical context can be safely used across the company.</p>

<p>AI can multiply output. It can also multiply bad assumptions, weak permissions, unclear ownership, and messy context. The companies that get this right will not be the ones that simply encourage everyone to use AI tools. They will be the ones that deliberately build the operating layer around AI use.</p>

<p>That operating layer also has to be designed for where the models are going, not only where they are today.</p>

<p>Model capability is moving too quickly for a company to rebuild its operating model from scratch every time the frontier changes. A workflow that feels barely possible today may become ordinary in a few months. A task that needs heavy human supervision now may become safe to delegate later if the context, permissions, evals, and review paths are already in place.</p>

<p>That matters internally and externally.</p>

<p>Internally, it means the CTO has to keep pushing the boundary of what the company asks AI to do. Some workflows may be too expensive, too brittle, or not quite possible today. But in this market, today’s bad fit can become tomorrow’s normal operating path. The company needs someone continuously testing that boundary, so it is ready to absorb the next jump in model capability.</p>

<p>Externally, it means building products and services with the same awareness. If you are building an AI-native product, the roadmap cannot only reflect what models can do this week. It has to account for what they are likely to make possible next, and where your product should be ready to absorb that capability.</p>

<p>This is not about guessing the future perfectly. It is about building a company that can adapt when the future arrives faster than expected.</p>

<p>My current view: the CTO’s job is not to be the smartest AI user in the company. It is to make the work itself smarter: sharper questions, clearer communication, stronger reviews, sounder decisions, and more consistent follow-through across the team. That is where productivity compounds.</p>

<hr />

<p><em>Originally published on <a href="https://www.linkedin.com/pulse/your-cto-got-10x-faster-did-company-kartikey-tanna-jeuof">LinkedIn</a>.</em></p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="ai" /><category term="cto" /><category term="leadership" /><summary type="html"><![CDATA[A note on what changes when AI stops being only the CTO's personal productivity layer and becomes part of how the company operates.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/your-cto-got-10x-faster/cover.jpg" /><media:content medium="image" url="https://www.kartikey.dev/assets/your-cto-got-10x-faster/cover.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">How to deploy a React app with Kamal (formerly known as MRSK) &amp;amp; GitHub Action</title><link href="https://www.kartikey.dev/2024/06/17/how-to-deploy-react-app-with-kamal-and-github-action.html" rel="alternate" type="text/html" title="How to deploy a React app with Kamal (formerly known as MRSK) &amp;amp; GitHub Action" /><published>2024-06-17T04:58:00+00:00</published><updated>2024-06-17T04:58:00+00:00</updated><id>https://www.kartikey.dev/2024/06/17/how-to-deploy-react-app-with-kamal-and-github-action</id><content type="html" xml:base="https://www.kartikey.dev/2024/06/17/how-to-deploy-react-app-with-kamal-and-github-action.html"><![CDATA[<p>I recently helped <a href="https://sidecarlearning.com" target="_blank">Sidecar Learning</a> move their legacy application built with React front-end and Rails back-end migrate from Heroku and AWS to VPS over at DigitalOcean.</p>

<p>This guide is outcome of that migration. React front-end was quite simple and do not have much moving parts so it’s quite simple to do this. If you are looking to deploy monolith application then you can read the following posts I have written:</p>

<ul>
  <li><a href="/2023/04/05/how-to-deploy-rails-app-and-postgres-with-mrsk-on-single-server.html">Deploy Rails app and Postgres with Kamal(previously MRSK) on single DigitalOcean server</a></li>
  <li><a href="/2023/04/09/how-to-deploy-multi-environment-staging-production-application-using-mrsk.html">How to deploy multi-environment(staging, production) application using Kamal(previously MRSK)</a></li>
  <li><a href="/2023/04/10/how-to-deploy-a-nodejs-application-using-mrsk.html">How to deploy a NodeJS application using Kamal (previously MRSK)</a></li>
</ul>

<h2 id="kamal-config">Kamal Config</h2>

<p>First, let’s create a simple <code class="language-plaintext highlighter-rouge">deploy.yml</code> for Kamal. The configuration is mostly boilerplate. I am using <a href="https://docs.docker.com/build/cache/backends/gha/" target="_blank">GHA cache</a> to speed up the deploys.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># config/deploy.yml</span>

<span class="na">service</span><span class="pi">:</span> <span class="s">react-app</span>
<span class="na">image</span><span class="pi">:</span> <span class="s">username/image-name</span>

<span class="na">servers</span><span class="pi">:</span>
  <span class="na">web</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">123.456.789.012</span>

<span class="na">registry</span><span class="pi">:</span>
  <span class="na">username</span><span class="pi">:</span> <span class="s">docker_username</span>
  <span class="na">password</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">KAMAL_REGISTRY_PASSWORD</span>

<span class="na">env</span><span class="pi">:</span>
  <span class="na">clear</span><span class="pi">:</span>
    <span class="na">FOO</span><span class="pi">:</span> <span class="s">BAR</span>
    <span class="na">NPM_CONFIG_PRODUCTION</span><span class="pi">:</span> <span class="no">false</span>

<span class="na">builder</span><span class="pi">:</span>
  <span class="na">multiarch</span><span class="pi">:</span> <span class="no">false</span>
  <span class="na">cache</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">gha</span>
    <span class="na">options</span><span class="pi">:</span> <span class="s">mode=max</span>
</code></pre></div></div>

<p>If you wish to, you can use “registry” cache as well. I have noticed that it’s faster by 5-10 seconds but if you are using free Docker Hub account then you only get one free image. That’s why I prefer to use “gha” as cache back-end. Kamal only <a href="https://kamal-deploy.org/docs/configuration/builders/#using-multistage-builder-cache" target="_blank">supports</a> “gha” and “registry”. If you would like to use the “registry” cache, use the following builder config:</p>
<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">builder</span><span class="pi">:</span>
  <span class="na">multiarch</span><span class="pi">:</span> <span class="no">false</span>
  <span class="na">cache</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">registry</span>
    <span class="na">options</span><span class="pi">:</span> <span class="s">mode=max,image-manifest=true,oci-mediatypes=true</span>
</code></pre></div></div>

<h2 id="dockerfile">Dockerfile</h2>

<p>Our app is using quite old version of NodeJS. This is why I like Kamal more than anything. No platform dependency or requirement to fulfil. You create your own environment and Kamal provides thin wrapper around the Docker commands. As simple as it could be.</p>

<p>Here, we first create a build step. Once the build is ready, no need to include all those node_modules in our final application. We keep it as small as possible so that it’s easier to perform operations.</p>

<p>In our app, we have a small Express app that serves the static file. That’s why I have created a separate <code class="language-plaintext highlighter-rouge">package.runtime.json</code> file. You can modify that part as per your own need. The next session will explain how the express server works.</p>

<div class="language-dockerfile highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Dockerfile</span>

<span class="k">FROM</span><span class="w"> </span><span class="s">node:11.10.1</span><span class="w"> </span><span class="k">as</span><span class="w"> </span><span class="s">build</span>

<span class="k">WORKDIR</span><span class="s"> /app</span>

<span class="k">ENV</span><span class="s"> NODE_ENV="production" \</span>
    NPM_CONFIG_PRODUCTION="false"

<span class="k">COPY</span><span class="s"> . .</span>

<span class="k">RUN </span>npm ci

<span class="k">RUN </span>npm run build

<span class="k">FROM</span><span class="s"> node:11.10.1</span>

<span class="k">WORKDIR</span><span class="s"> /app</span>

<span class="k">ENV</span><span class="s"> NODE_ENV="production" \</span>
    NPM_CONFIG_PRODUCTION="false"

<span class="k">COPY</span><span class="s"> --from=build /app/build ./build</span>
<span class="k">COPY</span><span class="s"> --from=build /app/server.js ./server.js</span>
<span class="k">COPY</span><span class="s"> --from=build /app/package.runtime.json ./package.json</span>

<span class="k">RUN </span>npm <span class="nb">install</span> <span class="nt">--production</span>

<span class="k">EXPOSE</span><span class="s"> 3000</span>

<span class="k">CMD</span><span class="s"> ["node", "server.js"]</span>
</code></pre></div></div>

<h2 id="express-server">Express Server</h2>

<p>We have a tiny express server that serves the static files with appropriate headers. We have configured Cloudflare to provide SSL support and cache the static assets. Only <code class="language-plaintext highlighter-rouge">index.html</code> file is not cached, and bundled assets will be served by this Express server only once. Then Cloudflare will take the load. All of this is deployed on our $4 DigitalOcean droplet and it is handling our moderately busy app very well.</p>

<p>I have <a href="https://webpack.js.org/guides/caching/" target="_blank">configured</a> the Webpack to generate bulid with hash, so with every new build, the new hash will rename the file - same as <a href="https://github.com/rails/propshaft/" target="_blank">Propshaft</a>.</p>

<p>I have added a route for Kamal healthcheck as well even though the health-check step has been <a href="https://github.com/basecamp/kamal/pull/740" target="_blank">removed</a> in Kamal 1.6.0.</p>

<div class="language-javascript highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">// server.js</span>

<span class="kd">const</span> <span class="nx">compression</span> <span class="o">=</span> <span class="nx">require</span><span class="p">(</span><span class="dl">'</span><span class="s1">compression</span><span class="dl">'</span><span class="p">);</span>
<span class="kd">const</span> <span class="nx">express</span> <span class="o">=</span> <span class="nx">require</span><span class="p">(</span><span class="dl">'</span><span class="s1">express</span><span class="dl">'</span><span class="p">);</span>
<span class="kd">const</span> <span class="nx">path</span> <span class="o">=</span> <span class="nx">require</span><span class="p">(</span><span class="dl">'</span><span class="s1">path</span><span class="dl">'</span><span class="p">);</span>
<span class="kd">const</span> <span class="nx">port</span> <span class="o">=</span> <span class="nx">process</span><span class="p">.</span><span class="nx">env</span><span class="p">.</span><span class="nx">PORT</span> <span class="o">||</span> <span class="mi">3000</span><span class="p">;</span>
<span class="kd">const</span> <span class="nx">app</span> <span class="o">=</span> <span class="nx">express</span><span class="p">();</span>

<span class="c1">// Use compression middleware</span>
<span class="nx">app</span><span class="p">.</span><span class="nx">use</span><span class="p">(</span><span class="nx">compression</span><span class="p">());</span>

<span class="c1">// Serve static files with cache control headers</span>
<span class="nx">app</span><span class="p">.</span><span class="nx">use</span><span class="p">(</span><span class="nx">express</span><span class="p">.</span><span class="kd">static</span><span class="p">(</span><span class="nx">path</span><span class="p">.</span><span class="nx">join</span><span class="p">(</span><span class="nx">__dirname</span><span class="p">,</span> <span class="dl">'</span><span class="s1">build</span><span class="dl">'</span><span class="p">),</span> <span class="p">{</span>
  <span class="na">maxAge</span><span class="p">:</span> <span class="dl">'</span><span class="s1">1d</span><span class="dl">'</span><span class="p">,</span> <span class="c1">// Cache for 1 day</span>
  <span class="na">setHeaders</span><span class="p">:</span> <span class="p">(</span><span class="nx">res</span><span class="p">,</span> <span class="nx">path</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
    <span class="c1">// Set cache-control headers based on file types</span>
    <span class="k">if</span> <span class="p">(</span><span class="nx">path</span><span class="p">.</span><span class="nx">endsWith</span><span class="p">(</span><span class="dl">'</span><span class="s1">.js</span><span class="dl">'</span><span class="p">))</span> <span class="p">{</span>
      <span class="nx">res</span><span class="p">.</span><span class="nx">setHeader</span><span class="p">(</span><span class="dl">'</span><span class="s1">Cache-Control</span><span class="dl">'</span><span class="p">,</span> <span class="dl">'</span><span class="s1">public, max-age=31536000</span><span class="dl">'</span><span class="p">);</span> <span class="c1">// 1 year</span>
    <span class="p">}</span> <span class="k">else</span> <span class="k">if</span> <span class="p">(</span><span class="nx">path</span><span class="p">.</span><span class="nx">endsWith</span><span class="p">(</span><span class="dl">'</span><span class="s1">.css</span><span class="dl">'</span><span class="p">))</span> <span class="p">{</span>
      <span class="nx">res</span><span class="p">.</span><span class="nx">setHeader</span><span class="p">(</span><span class="dl">'</span><span class="s1">Cache-Control</span><span class="dl">'</span><span class="p">,</span> <span class="dl">'</span><span class="s1">public, max-age=31536000</span><span class="dl">'</span><span class="p">);</span> <span class="c1">// 1 year</span>
    <span class="p">}</span> <span class="k">else</span> <span class="k">if</span> <span class="p">(</span><span class="nx">path</span><span class="p">.</span><span class="nx">endsWith</span><span class="p">(</span><span class="dl">'</span><span class="s1">.html</span><span class="dl">'</span><span class="p">))</span> <span class="p">{</span>
      <span class="nx">res</span><span class="p">.</span><span class="nx">setHeader</span><span class="p">(</span><span class="dl">'</span><span class="s1">Cache-Control</span><span class="dl">'</span><span class="p">,</span> <span class="dl">'</span><span class="s1">public, max-age=0</span><span class="dl">'</span><span class="p">);</span> <span class="c1">// No cache</span>
    <span class="p">}</span> <span class="k">else</span> <span class="p">{</span>
      <span class="nx">res</span><span class="p">.</span><span class="nx">setHeader</span><span class="p">(</span><span class="dl">'</span><span class="s1">Cache-Control</span><span class="dl">'</span><span class="p">,</span> <span class="dl">'</span><span class="s1">public, max-age=86400</span><span class="dl">'</span><span class="p">);</span> <span class="c1">// 1 day</span>
    <span class="p">}</span>
  <span class="p">}</span>
<span class="p">}));</span>

<span class="c1">// Kamal health check route</span>
<span class="nx">app</span><span class="p">.</span><span class="kd">get</span><span class="p">(</span><span class="dl">'</span><span class="s1">/up</span><span class="dl">'</span><span class="p">,</span> <span class="p">(</span><span class="nx">req</span><span class="p">,</span> <span class="nx">res</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
  <span class="nx">res</span><span class="p">.</span><span class="nx">send</span><span class="p">(</span><span class="s2">`&lt;!DOCTYPE html&gt;&lt;html&gt;&lt;body style="background-color: green"&gt;&lt;/body&gt;&lt;/html&gt;`</span><span class="p">);</span>
<span class="p">});</span>

<span class="c1">// Send all requests to index.html to handle routing in React Router</span>
<span class="nx">app</span><span class="p">.</span><span class="kd">get</span><span class="p">(</span><span class="dl">'</span><span class="s1">*</span><span class="dl">'</span><span class="p">,</span> <span class="p">(</span><span class="nx">req</span><span class="p">,</span> <span class="nx">res</span><span class="p">)</span> <span class="o">=&gt;</span> <span class="p">{</span>
  <span class="nx">res</span><span class="p">.</span><span class="nx">sendFile</span><span class="p">(</span><span class="nx">path</span><span class="p">.</span><span class="nx">resolve</span><span class="p">(</span><span class="nx">__dirname</span><span class="p">,</span> <span class="dl">'</span><span class="s1">build</span><span class="dl">'</span><span class="p">,</span> <span class="dl">'</span><span class="s1">index.html</span><span class="dl">'</span><span class="p">));</span>
<span class="p">});</span>

<span class="c1">// Start the server</span>
<span class="nx">app</span><span class="p">.</span><span class="nx">listen</span><span class="p">(</span><span class="nx">port</span><span class="p">,</span> <span class="p">()</span> <span class="o">=&gt;</span> <span class="p">{</span>
  <span class="nx">console</span><span class="p">.</span><span class="nx">log</span><span class="p">(</span><span class="s2">`Server is running on port </span><span class="p">${</span><span class="nx">port</span><span class="p">}</span><span class="s2">`</span><span class="p">);</span>
<span class="p">});</span>
</code></pre></div></div>

<p>We only need ExpressJS and the compression packages to run this small server. That’s why we are including only these two packages in the runtime package file.</p>

<p><code class="language-plaintext highlighter-rouge">package.runtime.json</code></p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"name"</span><span class="p">:</span><span class="w"> </span><span class="s2">"your-app"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"version"</span><span class="p">:</span><span class="w"> </span><span class="s2">"1.0.0"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"main"</span><span class="p">:</span><span class="w"> </span><span class="s2">"server.js"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"dependencies"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"compression"</span><span class="p">:</span><span class="w"> </span><span class="s2">"^1.7.4"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"express"</span><span class="p">:</span><span class="w"> </span><span class="s2">"^4.16.4"</span><span class="w">
  </span><span class="p">},</span><span class="w">
  </span><span class="nl">"scripts"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"start"</span><span class="p">:</span><span class="w"> </span><span class="s2">"node server.js"</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<h2 id="github-action">GitHub Action</h2>

<p>It’s a headache to run the deployment from your own machine. The following GitHub Actions config will solve it for you. I have added a concurrency config too that will let only one deploy run at a time. It’s useful when you make multiple commits in a short time.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># .github/workflows/deploy.yml</span>

<span class="na">name</span><span class="pi">:</span> <span class="s">Deploy to production</span>

<span class="c1"># To make sure that only one deploy runs at a time. Deploy lock will not let simultaneous deployments.</span>
<span class="na">concurrency</span><span class="pi">:</span>
  <span class="na">group</span><span class="pi">:</span> <span class="s">${{ github.workflow }}</span>

<span class="na">on</span><span class="pi">:</span>
  <span class="na">push</span><span class="pi">:</span>
    <span class="na">branches</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">master</span><span class="pi">]</span>

<span class="na">jobs</span><span class="pi">:</span>
  <span class="na">deploy</span><span class="pi">:</span>
    <span class="na">runs-on</span><span class="pi">:</span> <span class="s">ubuntu-latest</span>
    <span class="na">env</span><span class="pi">:</span>
      <span class="na">KAMAL_REGISTRY_PASSWORD</span><span class="pi">:</span> <span class="s">$</span>

    <span class="na">steps</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Set up Docker Buildx for cache</span>
        <span class="na">uses</span><span class="pi">:</span> <span class="s">docker/setup-buildx-action@v3</span>

      <span class="c1"># Since we are using GHA cache, we need to expose the cache to the runtime</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Expose GitHub Runtime for cache</span>
        <span class="na">uses</span><span class="pi">:</span> <span class="s">crazy-max/ghaction-github-runtime@v3</span>

      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Checkout code</span>
        <span class="na">uses</span><span class="pi">:</span> <span class="s">actions/checkout@v3</span>

      <span class="c1"># Ruby is only needed to install Kamal</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Set up Ruby</span>
        <span class="na">uses</span><span class="pi">:</span> <span class="s">ruby/setup-ruby@v1</span>
        <span class="na">with</span><span class="pi">:</span>
          <span class="na">ruby-version</span><span class="pi">:</span> <span class="s1">'</span><span class="s">3.3'</span>

      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Install dependencies</span>
        <span class="na">run</span><span class="pi">:</span> <span class="s">gem install kamal</span>

      <span class="c1"># This is to facilitate Kamal with the private key to access server(s)</span>
      <span class="pi">-</span> <span class="na">uses</span><span class="pi">:</span> <span class="s">webfactory/ssh-agent@v0.7.0</span>
        <span class="na">with</span><span class="pi">:</span>
          <span class="na">ssh-private-key</span><span class="pi">:</span> <span class="s">$</span>

      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Run deploy command</span>
        <span class="na">run</span><span class="pi">:</span> <span class="s">kamal deploy</span>
</code></pre></div></div>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="react" /><category term="kamal" /><category term="mrsk" /><category term="github" /><summary type="html"><![CDATA[I recently helped Sidecar Learning move their legacy application built with React front-end and Rails back-end migrate from Heroku and AWS to VPS over at DigitalOcean.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" /><media:content medium="image" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Understanding the role of the “schema.rb” file in Ruby on Rails development</title><link href="https://www.kartikey.dev/2023/08/06/understanding-the-role-of-the-schema-rb-file-in-ruby-on-rails-development.html" rel="alternate" type="text/html" title="Understanding the role of the “schema.rb” file in Ruby on Rails development" /><published>2023-08-06T00:00:00+00:00</published><updated>2023-08-06T00:00:00+00:00</updated><id>https://www.kartikey.dev/2023/08/06/understanding-the-role-of-the-schema-rb-file-in-ruby-on-rails-development</id><content type="html" xml:base="https://www.kartikey.dev/2023/08/06/understanding-the-role-of-the-schema-rb-file-in-ruby-on-rails-development.html"><![CDATA[<p>I recently published a <a href="https://www.linkedin.com/feed/update/urn:li:activity:7093289792351707136/" target="_blank">post in a Ruby on Rails group on LinkedIn</a> about a rake task I bring to most of my projects. This Rake task deletes the <code class="language-plaintext highlighter-rouge">schema.rb</code> file and regenerates it. I got many reactions from fellow developers and that motivated me to write this post.</p>

<h2 id="understanding-the-purpose-of-rails-schemarb-file">Understanding the Purpose of Rails’ schema.rb File</h2>

<p>The <code class="language-plaintext highlighter-rouge">schema.rb</code> file is essentially a blueprint of your Rails application’s database. Imagine your app as a house - the schema.rb is the floor plan you’d show your architect. It outlines your database’s structure, detailing tables, columns, their types, primary keys, and even relationships between them. Migrations update and generate this file automatically.</p>

<p>Why is it important? Think of it this way: a new team member joins and needs to understand your database structure. Rather than making them trawl through countless migrations (a process as thrilling as watching paint dry), they can reference the schema.rb file. This file provides a concise summary of your database structure, the Cliff Notes version, if you will.</p>

<p>The <code class="language-plaintext highlighter-rouge">schema.rb</code> file in a new Rails application contains the following comment:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># This file is auto-generated from the current state of the database. Instead  </span>
<span class="c1"># of editing this file, please use the migrations feature of Active Record to  </span>
<span class="c1"># incrementally modify your database, and then regenerate this schema definition.  </span>
<span class="c1">#  </span>
<span class="c1"># This file is the source Rails uses to define your schema when running \`bin/rails  </span>
<span class="c1"># db:schema:load\`. When creating a new database, \`bin/rails db:schema:load\` tends to  </span>
<span class="c1"># be faster and is potentially less error prone than running all of your  </span>
<span class="c1"># migrations from scratch. Old migrations may fail to apply correctly if those  </span>
<span class="c1"># migrations use external dependencies or application code.  </span>
<span class="c1">#  </span>
<span class="c1"># It's strongly recommended that you check this file into your version control system.</span>
</code></pre></div></div>

<h2 id="decoding-the-authority-over-the-database-in-rails">Decoding the Authority Over the Database in Rails</h2>

<p>The Rails docs’ interpretation of the authority over the database schema has seen notable changes over the years. To illustrate this, let’s look at two significant commits on the Rails GitHub.</p>

<p>The <a href="https://github.com/rails/rails/blob/9eeb00976d4b0a963c58117b46b7a5c6edcacc31/guides/source/migrations.md#what-are-schema-files-for" target="_blank">first version</a> of the docs from 2012 claimed that the <code class="language-plaintext highlighter-rouge">db/schema.rb</code> or an SQL file generated by Active Record was the authoritative source for your database schema.</p>

<blockquote>
  <p><strong>What are Schema Files for?</strong></p>

  <p>Migrations, mighty as they may be, are not the authoritative source for your database schema. <strong>That role falls to either <code class="language-plaintext highlighter-rouge">db/schema.rb</code> or an SQL file which Active Record generates by examining the database.</strong> They are not designed to be edited, they just represent the current state of the database.</p>

  <p><strong>There is no need (and it is error prone) to deploy a new instance of an app by replaying the entire migration history.</strong> It is much simpler and faster to just load into the database a description of the current schema.</p>
</blockquote>

<p>However, the <a href="https://github.com/rails/rails/blob/84718df86097442f85999d6f2e6f6b8b59724c3f/guides/source/active_record_migrations.md#what-are-schema-files-for" target="_blank">follow-up version</a> from 2018 which we read <a href="https://guides.rubyonrails.org/active_record_migrations.html#what-are-schema-files-for-questionmark" target="_blank">today</a> clearly states that your actual database remains the authoritative source.</p>

<blockquote>
  <p><strong>What are Schema Files for?</strong></p>

  <p>Migrations, mighty as they may be, are not the authoritative source for your database schema. <strong>Your database remains the authoritative source.</strong> By default, Rails generates <code class="language-plaintext highlighter-rouge">db/schema.rb</code> which attempts to capture the current state of your database schema.</p>

  <p>It tends to be faster and less error prone to create a new instance of your application’s database by loading the schema file via <code class="language-plaintext highlighter-rouge">rails db:schema:load</code> than it is to replay the entire migration history. <strong>Old migrations may fail to apply correctly if those migrations use changing external dependencies or rely on application code which evolves separately from your migrations.</strong></p>
</blockquote>

<p>The commit was made with the following comment from the contributors:</p>

<blockquote>
  <p>    <strong>Update <code class="language-plaintext highlighter-rouge">schema.rb</code> documentation [CI SKIP]</strong></p>

  <p>    The documentation previously claimed that `db/schema.rb` was “the<br />
    authoritative source for your database schema” while simultaneously<br />
    also acknowledging that the file is generated. These two statements are<br />
    incongruous and the guides accurately call out that many database<br />
    constructs are unsupported by `schema.rb`. <strong>This change updates the</strong><br />
    <strong>comment at the top of `schema.rb` to remove the assertion that the file</strong><br />
    <strong>is authoritative.</strong></p>

  <p>    The documentation also previously referred vaguely to “issues” when<br />
    re-running old migrations. This has been updated slightly to hint at the<br />
    types of problems that one can encounter with old migrations.</p>

  <p>    In sum, this change attempts to more accurately capture the pros, cons,<br />
    and shortcomings of the two schema formats in the guides and in the<br />
    comment at the top of `schema.rb`.</p>

  <p>    [Derek Prior &amp; Sean Griffin]</p>
</blockquote>

<p>While <code class="language-plaintext highlighter-rouge">db/schema.rb</code> and migrations play vital roles in managing your database structure, neither are the definitive descriptors of your schema. The <code class="language-plaintext highlighter-rouge">db/schema.rb</code> file is a Rails-generated snapshot of your database structure, and is useful for setting up new instances of your database quickly. Migrations, however, are used to implement incremental changes to your database over time.</p>

<p>As developers, ensuring your migrations are up-to-date and error-free is paramount. These migrations should be able to recreate <code class="language-plaintext highlighter-rouge">db/schema.rb</code> accurately. In the event of any breaking changes, such as class name alterations, best practices must be followed to ensure your migrations remain reversible and unaffected by such changes. Understanding these principles will help manage your database schema effectively in Rails.</p>

<h3 id="working-with-schemarb">Working with schema.rb </h3>

<p>While it might be tempting to manually modify <em>schema.rb</em>, resist the urge! Any changes should be made through migrations. This ensures that the <em>schema.rb</em> file can be regenerated correctly.</p>

<p>When working on a new or unreleased project, it might make sense to adjust existing migrations rather than creating new ones. This way, you keep the migration history lean and focused. However, if a project is already in production, creating new migrations for each database change is the standard practice. This ensures that your database changes are properly tracked, and each team member can understand when and why the database structure was changed.</p>

<p>In new and unreleased projects, I often opt to modify existing migrations rather than creating new ones. In older projects where migrations are being rectified, I use a custom rake task to streamline the process. Here’s a snippet of the task for resetting the database by dropping the schema:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># lib/tasks/complete_reset.rake</span>

<span class="n">namespace</span> <span class="ss">:db</span> <span class="k">do</span>
  <span class="n">desc</span> <span class="s1">'reset the database by dropping the schema'</span>
  <span class="n">task</span> <span class="ss">complete_reset: :environment</span> <span class="k">do</span>
   <span class="k">raise</span> <span class="k">unless</span> <span class="no">Rails</span><span class="p">.</span><span class="nf">env</span><span class="p">.</span><span class="nf">local?</span>
    
    <span class="no">FileUtils</span><span class="p">.</span><span class="nf">rm_f</span><span class="p">(</span><span class="s1">'db/schema.rb'</span><span class="p">)</span>
    <span class="no">Rake</span><span class="o">::</span><span class="no">Task</span><span class="p">[</span><span class="s1">'db:drop'</span><span class="p">].</span><span class="nf">invoke</span>
    <span class="no">Rake</span><span class="o">::</span><span class="no">Task</span><span class="p">[</span><span class="s1">'db:create'</span><span class="p">].</span><span class="nf">invoke</span>
    <span class="no">Rake</span><span class="o">::</span><span class="no">Task</span><span class="p">[</span><span class="s1">'db:migrate'</span><span class="p">].</span><span class="nf">invoke</span>
    <span class="no">Rake</span><span class="o">::</span><span class="no">Task</span><span class="p">[</span><span class="s1">'db:seed'</span><span class="p">].</span><span class="nf">invoke</span>
    <span class="no">Rake</span><span class="o">::</span><span class="no">Task</span><span class="p">[</span><span class="s1">'dev:prime'</span><span class="p">].</span><span class="nf">invoke</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>This task handles the removal of db/schema.rb, drops the database, creates it anew, migrates and seeds it, and primes it for development. Be extremely cautious when choosing the environment this task is applied to; it should not be used on deployed servers once your app has hit staging or production stages.</p>

<p>This task becomes particularly useful in the early stages of a project when specifications are frequently changing. When switching between branches, conflicts in the schema.rb file can often arise due to these rapid changes. This task helps you avoid creating excessive migrations and ensures a smooth, efficient development process by resolving such conflicts.</p>

<p>It’s important to note that this task also invokes another task, dev:prime. This primes the development database with test data, providing a consistent starting state after a reset. So, firing complete_reset on the development environment not only clears any schema conflicts, but also populates your database with test data for a fresh start.</p>

<h2 id="faqs">FAQs</h2>

<h3 id="should-i-modify-the-schemarb-file-manually">Should I modify the <code class="language-plaintext highlighter-rouge">schema.rb</code> file manually?</h3>

<p>As a rule of thumb, you <strong>should not</strong> manually modify the <code class="language-plaintext highlighter-rouge">schema.rb</code> file. Instead, you should use <a href="https://guides.rubyonrails.org/active_record_migrations.html#what-are-schema-files-for-questionmark" target="_blank">ActiveRecord Migrations</a> to alter your database schema. This ensures that changes are properly tracked and the <code class="language-plaintext highlighter-rouge">schema.rb</code> is updated correctly. In rare, exceptional cases with legacy code or failed migrations, direct modification could be considered but it’s a risky approach and should only be done with extreme caution.</p>

<h3 id="what-are-some-best-practices-for-managing-the-schemarb-file-in-a-team-environment">What are some best practices for managing the <code class="language-plaintext highlighter-rouge">schema.rb</code> file in a team environment?</h3>

<ol>
  <li><strong>Version Control</strong>: Always keep the <code class="language-plaintext highlighter-rouge">schema.rb</code> file in your version control system to keep track of its changes over time.</li>
  <li><strong>Don’t Modify Manually</strong>: Avoid making manual modifications to the <code class="language-plaintext highlighter-rouge">schema.rb</code> file. Use ActiveRecord migrations instead.</li>
  <li><strong>Review Changes</strong>: Before committing changes to the <code class="language-plaintext highlighter-rouge">schema.rb</code> file, review them to make sure they align with the changes made in your migrations.</li>
  <li><strong>Sync with Database</strong>: Always make sure your <code class="language-plaintext highlighter-rouge">schema.rb</code> file is synchronized with the current state of your database schema.</li>
</ol>

<h3 id="what-happens-if-the-schemarb-file-is-deleted-or-modified">What happens if the <code class="language-plaintext highlighter-rouge">schema.rb</code> file is deleted or modified?</h3>

<p>If the <code class="language-plaintext highlighter-rouge">schema.rb</code> file is deleted or modified manually, it may lead to inconsistencies between the actual state of your database and the Rails application’s understanding of the database schema. This can lead to unexpected errors or bugs in your application. Therefore, it is advised not to delete or manually modify the <code class="language-plaintext highlighter-rouge">schema.rb</code> file.</p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="rails" /><category term="postgresql" /><summary type="html"><![CDATA[I recently published a post in a Ruby on Rails group on LinkedIn about a rake task I bring to most of my projects. This Rake task deletes the schema.rb file and regenerates it. I got many reactions from fellow developers and that motivated me to write this post.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" /><media:content medium="image" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">How to enable Traefik dashboard with Kamal (previously MRSK)</title><link href="https://www.kartikey.dev/2023/04/12/how-to-enable-traefik-dashboard-with-mrsk.html" rel="alternate" type="text/html" title="How to enable Traefik dashboard with Kamal (previously MRSK)" /><published>2023-04-12T13:10:00+00:00</published><updated>2023-04-12T13:10:00+00:00</updated><id>https://www.kartikey.dev/2023/04/12/how-to-enable-traefik-dashboard-with-mrsk</id><content type="html" xml:base="https://www.kartikey.dev/2023/04/12/how-to-enable-traefik-dashboard-with-mrsk.html"><![CDATA[<p><a href="https://kamal-deploy.org/" target="_blank"> Kamal </a> uses Traefik as a dynamic reverse-proxy. Traefik has a beautiful <a href="https://doc.traefik.io/traefik/operations/dashboard/" target="_blank"> dashboard </a> to visually display the configuration. Kamal is not configured to show the dashboard by default.</p>

<p>Traefik dashboard can run in two modes - secure and insecure. Traefik recommends secure mode but this post wil cover how to enable both the modes.</p>

<p>First, let’s see the unsecure mode. Unsecure mode is very easy to configure. It is unsecure because it exposes Traefix API on the <a href="https://doc.traefik.io/traefik/routing/entrypoints/" target="_blank"> entrypoint </a>. It means that after configuring the dashboard in unsecure mode, the dashboard will be available on the port 8080 of the host.</p>

<p>Adding the following snippet in the <code class="language-plaintext highlighter-rouge">config/deploy.yml</code> file will enable the unsecure dashboard.</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># config/deploy.yml</span>
<span class="na">traefik</span><span class="pi">:</span>
  <span class="na">options</span><span class="pi">:</span>
    <span class="na">publish</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">8080:8080</span>
  <span class="na">args</span><span class="pi">:</span>
    <span class="na">api.dashboard</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">api.insecure</span><span class="pi">:</span> <span class="no">true</span>
</code></pre></div></div>
<p>After adding the configuration, run the <code class="language-plaintext highlighter-rouge">kamal traefik reboot</code> command to apply the configuration. This command will stop, remove and start new container again with the latest configuration. The dashboard should be visible on the port <code class="language-plaintext highlighter-rouge">8080</code> of the host server now e.g. http://99.99.99.99:8080</p>

<p>Now, let’s see about the secure mode. It’s called secure mode because the API is not expose on the entrypoint. We need to create a router rule that uses <code class="language-plaintext highlighter-rouge">api@internal</code> service. Let’s look at the configuration for the secure model.</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">traefik</span><span class="pi">:</span>
  <span class="na">options</span><span class="pi">:</span>
    <span class="na">publish</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">8080:8080</span>
  <span class="na">args</span><span class="pi">:</span>
    <span class="na">api.dashboard</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">labels</span><span class="pi">:</span>
    <span class="na">traefik.enable</span><span class="pi">:</span> <span class="s2">"</span><span class="s">true"</span>
    <span class="na">traefik.http.routers.dashboard.rule</span><span class="pi">:</span> <span class="s">Host(`traefik.example.com`) &amp;&amp; (PathPrefix(`/api`) || PathPrefix(`/dashboard`))</span>
    <span class="na">traefik.http.routers.dashboard.service</span><span class="pi">:</span> <span class="s2">"</span><span class="s">api@internal"</span>
    <span class="na">traefik.http.routers.dashboard.middlewares</span><span class="pi">:</span> <span class="s2">"</span><span class="s">auth"</span>
    <span class="na">traefik.http.middlewares.auth.basicauth.users</span><span class="pi">:</span> <span class="s">test:$2y$05$H2o72tMaO.TwY1wNQUV1K.fhjRgLHRDWohFvUZOJHBEtUXNKrqUKi</span>
</code></pre></div></div>
<p>Here, we have configured Traefik dynamically with help of Docker labels. First of we have created a router. Then we attached the router with the <code class="language-plaintext highlighter-rouge">api@internal</code> service because in the secure mode we have to do this manually. After that, we added the auth middleware to Trafeik. In the last, we conifgured this <code class="language-plaintext highlighter-rouge">auth</code> middleware to use <a href="https://doc.traefik.io/traefik/middlewares/http/basicauth/" target="_blank">HTTP Basic Authentication</a> and provided it with the credentials. You can read more about the rules in the details on the Traefik <a href="https://doc.traefik.io/traefik/routing/routers/" target="_blank"> docs </a>.</p>

<p>The credentials are in the “username:hashed_password” format. The credentials are generated with the <code class="language-plaintext highlighter-rouge">htpasswd</code> command. Let’s say you want to create a user with the username “admin” and the password “super_strong_password” then you can use the following command:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>htpasswd <span class="nt">-nb</span> admin super_strong_password
<span class="c"># output: admin:$apr1$2FGO09Gu$PSZdmmJqyrXWYvidWAm6p0</span>
</code></pre></div></div>

<p>You will get the password hash in the output. Just copy paste the output with the username:password in the labels. The official Traefik docs mention that you need to escape the <code class="language-plaintext highlighter-rouge">$</code> character but you don’t need if you are using Kamal but Kamal <a href="https://github.com/mrsked/mrsk#using-shell-expansion" target="_blank"> escapes </a> the <code class="language-plaintext highlighter-rouge">$</code> sign for these labels.</p>

<p>That’s it! Don’t forget to reboot the Trafeik container with the <code class="language-plaintext highlighter-rouge">kamal traefik reboot</code> comamnd. After that, the dashboard should be accessible on the http://traefik.example.com/dashboard endpoint.</p>

<p>P.S. I would not recommend running the dashboard permanently if you are using a small single server with multple apps. Because that would eat up the valuable server resources.</p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="mrsk" /><category term="kamal" /><summary type="html"><![CDATA[Kamal uses Traefik as a dynamic reverse-proxy. Traefik has a beautiful dashboard to visually display the configuration. Kamal is not configured to show the dashboard by default.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/traefik-dashboard.png" /><media:content medium="image" url="https://www.kartikey.dev/assets/traefik-dashboard.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">How to deploy a NodeJS application using Kamal (previously MRSK)</title><link href="https://www.kartikey.dev/2023/04/10/how-to-deploy-a-nodejs-application-using-mrsk.html" rel="alternate" type="text/html" title="How to deploy a NodeJS application using Kamal (previously MRSK)" /><published>2023-04-10T08:25:00+00:00</published><updated>2023-04-10T08:25:00+00:00</updated><id>https://www.kartikey.dev/2023/04/10/how-to-deploy-a-nodejs-application-using-mrsk</id><content type="html" xml:base="https://www.kartikey.dev/2023/04/10/how-to-deploy-a-nodejs-application-using-mrsk.html"><![CDATA[<p><a href="https://kamal-deploy.org/">Kamal</a> is created by DHH - founder of Rails, but the tool is not limited to deploy only Rails applications. Kamal is a simple tool that automates some Docker related commands. That is why it can support any platform/language. In this post, let’s see how to deploy a NodeJS application on a small DigitalOcean VPS using Kamal.</p>

<p>First of all, let’s generate an express app. I installed <a href="https://expressjs.com/en/starter/generator.html" target="_blank"><code class="language-plaintext highlighter-rouge">express-generator</code></a> and generated a new app using the <code class="language-plaintext highlighter-rouge">express express-app</code> command.</p>

<p>Then let’s create a Dockerfile:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>FROM node:16

# Create app directory
WORKDIR /usr/src/app

# Install app dependencies
# A wildcard is used to ensure both package.json AND package-lock.json are copied
# where available (npm@5+)
COPY package*.json ./

RUN npm install
# If you are building your code for production
# RUN npm ci --omit=dev

# Bundle app source
COPY . .

EXPOSE 3000
CMD [ "node", "bin/www" ]
</code></pre></div></div>

<p>Now, let’s use Kamal to generate the config files. Make sure you have Kamal installed on your machine. If not, you can <a href="https://kamal-deploy.org/docs/installation"> follow these instructions </a> on README.</p>

<p>Let’s init the configuration with <code class="language-plaintext highlighter-rouge">kamal init</code>. It will create <code class="language-plaintext highlighter-rouge">config/deploy.yml</code> and <code class="language-plaintext highlighter-rouge">.env</code> files in your root directory. My config file looks like this:</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">service</span><span class="pi">:</span> <span class="s">express-app</span>

<span class="na">image</span><span class="pi">:</span> <span class="s">user/express-app</span>
<span class="na">servers</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s">146.190.86.77</span>

<span class="na">registry</span><span class="pi">:</span>
  <span class="na">username</span><span class="pi">:</span> <span class="s">user</span>
  <span class="na">password</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">KAMAL_REGISTRY_PASSWORD</span>

<span class="na">healthcheck</span><span class="pi">:</span>
  <span class="na">path</span><span class="pi">:</span> <span class="s">/</span>
  <span class="na">port</span><span class="pi">:</span> <span class="m">3000</span>
</code></pre></div></div>

<p>The config file I have created here is minimal. It defines a service, provides the server IP, Docker Hub registry info and healthcheck information. After successful deploy, Kamal will ping the “/” path on port “3000” and will expect the “200 OK” response from the server.</p>

<p>Now, let’s deploy the app with the <code class="language-plaintext highlighter-rouge">kamal deploy</code> command. Kamal will deploy your app and you can check if it is live or not by entering the server IP address in the browser. If you want to connect your app with the database, or host multiple environment of the application like staging, production then you can check out my <a href="https://www.kartikey.dev/tag/mrsk/"> previous posts </a>. They are platform agnostic and applicable on NodeJS apps as well.</p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="mrsk" /><category term="kamal" /><category term="nodejs" /><summary type="html"><![CDATA[Kamal is created by DHH - founder of Rails, but the tool is not limited to deploy only Rails applications. Kamal is a simple tool that automates some Docker related commands. That is why it can support any platform/language. In this post, let’s see how to deploy a NodeJS application on a small DigitalOcean VPS using Kamal.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" /><media:content medium="image" url="https://www.kartikey.dev/assets/me-social.jpg?v=1" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">How to deploy multi-environment(staging, production) application using Kamal(previously MRSK)</title><link href="https://www.kartikey.dev/2023/04/09/how-to-deploy-multi-environment-staging-production-application-using-mrsk.html" rel="alternate" type="text/html" title="How to deploy multi-environment(staging, production) application using Kamal(previously MRSK)" /><published>2023-04-09T08:45:00+00:00</published><updated>2023-04-09T08:45:00+00:00</updated><id>https://www.kartikey.dev/2023/04/09/how-to-deploy-multi-environment-staging-production-application-using-mrsk</id><content type="html" xml:base="https://www.kartikey.dev/2023/04/09/how-to-deploy-multi-environment-staging-production-application-using-mrsk.html"><![CDATA[<p>In the <a href="https://www.kartikey.dev/2023/04/05/how-to-deploy-rails-app-and-postgres-with-mrsk-on-single-server.html" target="_blank">previous post</a>, I described how to host a Rails app and a database on a single server. This post will describe what if you want to host multiple environments i.e. staging, production of the same application using <a href="https://kamal-deploy.org/" target="_blank">Kamal</a>.</p>

<p>Kamal uses <a href="https://traefik.io/" target="_blank">Traefik</a> as a reverse proxy. It means that any incoming request will be handled by Traefik. Traefik will handover the request to appropriate server and Docker container based on the configuration. For example, let’s assume that we have deployed the staging and the production version of our apps on the server. Then we have to configure Traefik in such a way that it points “staging.myapp.com” and “production.myapp.com” to the staging and the production Docker containers respectively.</p>

<p>Kamal uses Traefik with “docker” as a <a href="https://doc.traefik.io/traefik/providers/overview/" target="_blank">provider</a>. Traefik <a href="https://doc.traefik.io/traefik/routing/routers/#rule" taget="_blank">rules</a> are configured by providing certain lables to Docker containers. You can read more about it in their <a href="https://doc.traefik.io/traefik/providers/docker/" target="_blank">docs</a>.</p>

<p>Let’s start configuring Kamal. Kamal has a feature called <a href="https://github.com/mrsked/mrsk/pull/71" target="_blank">“destination”</a>, we will use that to create two separate destinations - “staging” and “production”. First, we will create the <code class="language-plaintext highlighter-rouge">config/deploy.yml</code> file with common options like service name, image name, registry, common environment variables, and Postgresql database as acessory.</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># config/deploy.yml</span>
<span class="na">service</span><span class="pi">:</span> <span class="s">myapp</span>
<span class="na">image</span><span class="pi">:</span> <span class="s">user/myapp</span>

<span class="na">registry</span><span class="pi">:</span>
  <span class="na">username</span><span class="pi">:</span> <span class="s">user</span>
  <span class="na">password</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">KAMAL_REGISTRY_PASSWORD</span>

<span class="na">env</span><span class="pi">:</span>
  <span class="na">clear</span><span class="pi">:</span>
    <span class="na">DB_HOST</span><span class="pi">:</span> <span class="s">99.99.99.99</span>
  <span class="na">secret</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">RAILS_MASTER_KEY</span>
    <span class="pi">-</span> <span class="s">POSTGRES_PASSWORD</span>

<span class="na">accessories</span><span class="pi">:</span>
  <span class="na">db</span><span class="pi">:</span>
    <span class="na">image</span><span class="pi">:</span> <span class="s">postgres:15</span>
    <span class="na">host</span><span class="pi">:</span> <span class="s">99.99.99.99</span>
    <span class="na">port</span><span class="pi">:</span> <span class="m">5432</span>
    <span class="na">env</span><span class="pi">:</span>
      <span class="na">clear</span><span class="pi">:</span>
        <span class="na">POSTGRES_USER</span><span class="pi">:</span> <span class="s1">'</span><span class="s">myapp_db_user'</span>
      <span class="na">secret</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s">POSTGRES_PASSWORD</span>
    <span class="na">directories</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">data:/var/lib/postgresql/data</span>
</code></pre></div></div>

<h4 id="staging-config">Staging config</h4>
<p>Now, let’s create a destination named “staging” with the <code class="language-plaintext highlighter-rouge">config/deploy.staging.yml</code> file.</p>
<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># config/deploy.staging.yml</span>
<span class="na">servers</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s">99.99.99.99</span>

<span class="na">labels</span><span class="pi">:</span>
  <span class="na">traefik.http.routers.myapp-web-staging.rule</span><span class="pi">:</span> <span class="s">Host(`staging.myapp.com`)</span>

<span class="na">env</span><span class="pi">:</span>
  <span class="na">clear</span><span class="pi">:</span>
    <span class="na">POSTGRES_DB</span><span class="pi">:</span> <span class="s">myapp_staging</span>
    <span class="na">IS_STAGING</span><span class="pi">:</span> <span class="no">true</span>
</code></pre></div></div>

<p>In this file we have declared the server for the staging environment, environment variable spcific to the environment and we have used the <code class="language-plaintext highlighter-rouge">labels</code> key that will attach the labels to the staging Docker container.</p>

<p>Let’s understand these rules with little more details. Kamal applies some default Traefik labels to each container in the “service-role-destination” format. With the help of these labels Traefik defines a <a href="https://doc.traefik.io/traefik/routing/services/" target="_blank">service</a> (not to be confused with Kamal service). With the rule mentioned in the <code class="language-plaintext highlighter-rouge">deploy.staging.yml</code> file above, we are overriding the default labels. Since we have not specified any role, Kamal will assign the web role to the service. Anyways, there has to have one “web” role if we are specifying roles.</p>

<p>Don’t forget to replace “staging.myapp.com” with your domain. The domain should be configured to point to the IP of the server.</p>

<h4 id="production-config">Production config</h4>
<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># config/deploy.production.yml</span>
<span class="na">servers</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s">99.99.99.99</span>

<span class="na">labels</span><span class="pi">:</span>
  <span class="na">traefik.http.routers.myapp-web-production.rule</span><span class="pi">:</span> <span class="s">Host(`rails.myapp.com`)</span>

<span class="na">env</span><span class="pi">:</span>
  <span class="na">clear</span><span class="pi">:</span>
    <span class="na">POSTGRES_DB</span><span class="pi">:</span> <span class="s">myapp_production</span>
</code></pre></div></div>
<p>The <code class="language-plaintext highlighter-rouge">deploy.production.yml</code> is similar to the staging configuration. Since we are going to deploy both the staging and the production as well as Postgresql(the database) on the same server, the same IP is configured under the <code class="language-plaintext highlighter-rouge">hosts</code> key. Again, don’t forget to configure your domain.</p>

<p>That’s it! You should have both the staging and the production as well as the database deployed on the same or different server(s) and accessible from the domains you have set for each environment!</p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="mrsk" /><category term="kamal" /><category term="rails" /><category term="postgresql" /><summary type="html"><![CDATA[In the previous post, I described how to host a Rails app and a database on a single server. This post will describe what if you want to host multiple environments i.e. staging, production of the same application using Kamal.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/how-to-deploy-multi-environment-staging-production-application-using-mrsk.png" /><media:content medium="image" url="https://www.kartikey.dev/assets/how-to-deploy-multi-environment-staging-production-application-using-mrsk.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Deploy Rails app and Postgres with Kamal(previously MRSK) on single DigitalOcean server</title><link href="https://www.kartikey.dev/2023/04/05/how-to-deploy-rails-app-and-postgres-with-mrsk-on-single-server.html" rel="alternate" type="text/html" title="Deploy Rails app and Postgres with Kamal(previously MRSK) on single DigitalOcean server" /><published>2023-04-05T13:08:00+00:00</published><updated>2023-04-05T13:08:00+00:00</updated><id>https://www.kartikey.dev/2023/04/05/how-to-deploy-rails-app-and-postgres-with-mrsk-on-single-server</id><content type="html" xml:base="https://www.kartikey.dev/2023/04/05/how-to-deploy-rails-app-and-postgres-with-mrsk-on-single-server.html"><![CDATA[<p>For me, it’s been always cumbersome to host a Rails side project or personal application. Sure, Heroku is straightforward but it’s not as cheap as I would like it to be. And I don’t like the uptime limitation their free plan has. I have been making my way through Dokku and Capistrano. Luckily, a new door opened when <a href="https://kamal-deploy.org/">Kamal</a> was launched by DHH recently.</p>

<p>In this post, I am not getting into how Kamal works and the benefits of using it. DHH has created this fantastic <a href="https://www.youtube.com/watch?v=LL1cV2FXZ5I">introduction video</a> for that.</p>

<p>Kamal is capable to deploy applications on multiple servers as well as a single server. In this post, I will describe how we can deploy a Rails application and Postgresql on a single VPS.</p>

<p>First of all, install and init Kamal on your local machine with instructions on the <a href="https://github.com/basecamp/kamal#readme">README</a>.</p>

<p>The key to the single server setup is to use the same hosts for the <code class="language-plaintext highlighter-rouge">web</code> as well as <code class="language-plaintext highlighter-rouge">accessories</code>. Here is what the <code class="language-plaintext highlighter-rouge">deploy.yml</code> file looks like for that setup:</p>
<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">service</span><span class="pi">:</span> <span class="s">my-app</span>
<span class="na">image</span><span class="pi">:</span> <span class="s">user/my-app</span>

<span class="na">servers</span><span class="pi">:</span>
  <span class="na">web</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">134.209.111.91</span>

<span class="na">registry</span><span class="pi">:</span>
  <span class="na">username</span><span class="pi">:</span> <span class="s">tannakartikey</span>
  <span class="na">password</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">KAMAL_REGISTRY_PASSWORD</span>

<span class="na">env</span><span class="pi">:</span>
  <span class="na">clear</span><span class="pi">:</span>
    <span class="na">DB_HOST</span><span class="pi">:</span> <span class="s">134.209.111.91</span>
  <span class="na">secret</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">RAILS_MASTER_KEY</span>
    <span class="pi">-</span> <span class="s">POSTGRES_PASSWORD</span>

<span class="na">accessories</span><span class="pi">:</span>
  <span class="na">db</span><span class="pi">:</span>
    <span class="na">image</span><span class="pi">:</span> <span class="s">postgres:15</span>
    <span class="na">host</span><span class="pi">:</span> <span class="s">134.209.111.91</span>
    <span class="na">port</span><span class="pi">:</span> <span class="m">5432</span>
    <span class="na">env</span><span class="pi">:</span>
      <span class="na">clear</span><span class="pi">:</span>
        <span class="na">POSTGRES_USER</span><span class="pi">:</span> <span class="s1">'</span><span class="s">my_app'</span>
        <span class="na">POSTGRES_DB</span><span class="pi">:</span> <span class="s1">'</span><span class="s">my_app_production'</span>
      <span class="na">secret</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s">POSTGRES_PASSWORD</span>
    <span class="na">directories</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">data:/var/lib/postgresql/data</span>
</code></pre></div></div>

<p>I am using the default <a href="https://github.com/tannakartikey/rails_71_mrsk_deploy/blob/2d138e10b2c87ec0bccc382ae06ce6e71c6f7187/Dockerfile"><code class="language-plaintext highlighter-rouge">Dockerfile</code></a> that is generated with Rails 7.1. Create and place the Dockerfile in your root directory if it does not exist already. You also need to create a <a href="https://github.com/tannakartikey/rails_71_mrsk_deploy/commit/2d138e10b2c87ec0bccc382ae06ce6e71c6f7187#diff-e9cbb0224c4a3d23a6019ba557e0cd568c1ad5e1582ff1e335fb7d99b7a1055d"><code class="language-plaintext highlighter-rouge">.env</code></a> file in the root of the repository and also need to make minor changes in your <a href="https://github.com/tannakartikey/rails_71_mrsk_deploy/commit/2d138e10b2c87ec0bccc382ae06ce6e71c6f7187#diff-5a674c769541a71f2471a45c0e9dde911b4455344e3131bddc5a363701ba6325"><code class="language-plaintext highlighter-rouge">config/database.yml</code></a> file.</p>

<p>I have created this sample <a href="https://github.com/tannakartikey/rails_71_mrsk_deploy">repository</a> that has all the code described in this post. This <a href="https://github.com/tannakartikey/rails_71_mrsk_deploy/commit/2d138e10b2c87ec0bccc382ae06ce6e71c6f7187">commit</a> holds all the Kamal setup-related changes.</p>

<p>Be sure NOT to include your <code class="language-plaintext highlighter-rouge">.env</code> file in Git or your <code class="language-plaintext highlighter-rouge">Dockerfile</code>. If you are using Docker Hub or any other registry, make sure to make the image private because it holds a copy of the application code.</p>

<p>Next, we need to set up the server since we are deploying to the server for the first time. We can do it with:</p>
<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bin/kamal setup
</code></pre></div></div>
<p>The <code class="language-plaintext highlighter-rouge">setup</code> command will set up all the accessories and deploy the app on the server.</p>

<p>That’s it! You should have a running Rails app on the server which is connected to Postgresql on the same server. For subsequent deploy you can use <code class="language-plaintext highlighter-rouge">kamal deploy</code> or <code class="language-plaintext highlighter-rouge">kamal redeploy</code> based on your needs.</p>

<p>I have been using the USD4 droplet on DigitalOcean. If you are using a similar configuration I would recommend creating a <a href="https://www.digitalocean.com/community/tutorials/how-to-add-swap-space-on-ubuntu-20-04">swap</a> partition on the server. I am assuming that if you are doing this, you are not expecting loads of traffic on day one. But without a swap partition, some simple operations like migrating the database may also fail.</p>

<p>It can also be possible to host the same code multiple times for different environments i.e. staging, production etc. For that, the <a href="https://github.com/mrsked/mrsk/pull/99">“role”</a> and <a href="https://github.com/mrsked/mrsk/pull/71">“destination”</a> functionality of Kamal can be used. I might cover that in a separate post.</p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="mrsk" /><category term="kamal" /><category term="rails" /><category term="postgresql" /><summary type="html"><![CDATA[For me, it’s been always cumbersome to host a Rails side project or personal application. Sure, Heroku is straightforward but it’s not as cheap as I would like it to be. And I don’t like the uptime limitation their free plan has. I have been making my way through Dokku and Capistrano. Luckily, a new door opened when Kamal was launched by DHH recently.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/deploy-with-mrsk.png" /><media:content medium="image" url="https://www.kartikey.dev/assets/deploy-with-mrsk.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Memory efficient way of reading and downloading a large file in Ruby</title><link href="https://www.kartikey.dev/2020/10/02/memory-efficient-way-reading-and-downloading-file-in-ruby.html" rel="alternate" type="text/html" title="Memory efficient way of reading and downloading a large file in Ruby" /><published>2020-10-02T00:00:00+00:00</published><updated>2020-10-02T00:00:00+00:00</updated><id>https://www.kartikey.dev/2020/10/02/memory-efficient-way-reading-and-downloading-file-in-ruby</id><content type="html" xml:base="https://www.kartikey.dev/2020/10/02/memory-efficient-way-reading-and-downloading-file-in-ruby.html"><![CDATA[<h3 id="to-read-a-large-file-from-the-disk">To read a large file from the disk</h3>

<p><a href="https://ruby-doc.org/core-2.7.1/IO.html#method-c-foreach" target="\_blank"><code class="language-plaintext highlighter-rouge">File.foreach</code></a> method reads the file line by line; that is why it is safe to use for large files.<br />
It can accept the block to execute each line of a file.</p>

<p>Example:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">File</span><span class="p">.</span><span class="nf">foreach</span><span class="p">(</span><span class="s1">'example.jsonl'</span><span class="p">)</span> <span class="p">{</span> <span class="o">|</span><span class="n">line</span><span class="o">|</span> <span class="no">JSON</span><span class="p">.</span><span class="nf">parse</span><span class="p">(</span><span class="n">line</span><span class="p">)</span> <span class="p">}</span>
</code></pre></div></div>

<p>However, in the Ruby documentation, you will not find this method defined on the <a href="https://ruby-doc.org/core-2.7.1/File.html" target="\_blank"><code class="language-plaintext highlighter-rouge">File</code></a> class. It is defined on <a href="https://ruby-doc.org/core-2.7.1/IO.html" target="\_blank"><code class="language-plaintext highlighter-rouge">IO</code></a>, which is a superclass of <a href="https://ruby-doc.org/core-2.7.1/File.html" target="\_blank"><code class="language-plaintext highlighter-rouge">File</code></a>.</p>

<h3 id="to-download-the-large-files-from-the-internet">To download the large files from the Internet</h3>

<p>We can use <a href="https://ruby-doc.org/core-2.7.1/IO.html#method-c-copy_stream" target="\_blank"><code class="language-plaintext highlighter-rouge">IO.copy_stream</code></a> to download the large files from the Internet. It will create a stream instead of loading the whole file into memory before writing.</p>

<p>Example:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">IO</span><span class="p">.</span><span class="nf">copy_stream</span><span class="p">(</span><span class="nb">open</span><span class="p">(</span><span class="s1">'http://example.com/file.jsonl'</span><span class="p">),</span> <span class="s1">'file.jsonl'</span><span class="p">)</span>
</code></pre></div></div>

<p>To sum it up…</p>

<p>Memory friendly methods:<br />
<a href="https://ruby-doc.org/core-2.7.1/IO.html#method-c-foreach" target="\_blank"><code class="language-plaintext highlighter-rouge">File.foreach</code></a>, <a href="https://ruby-doc.org/core-2.7.1/IO.html#method-c-copy_stream"><code class="language-plaintext highlighter-rouge">IO.copy_stream</code></a></p>

<p>Other methods to read a file:<br />
<a href="https://ruby-doc.org/core-2.7.1/IO.html#method-c-read"><code class="language-plaintext highlighter-rouge">File.read</code></a>, <a href="https://ruby-doc.org/core-2.7.1/IO.html#method-c-readlines"><code class="language-plaintext highlighter-rouge">File.readlines</code></a></p>]]></content><author><name>Kartikey Tanna</name><email>tannakartikey@gmail.com</email></author><category term="ruby" /><summary type="html"><![CDATA[To read a large file from the disk]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://www.kartikey.dev/assets/files_image.jpg" /><media:content medium="image" url="https://www.kartikey.dev/assets/files_image.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>